Zvi (Don't Worry About the Vase)·1 month ago·
24
● 5 sources
Claude Fable 5.1 was released alongside discussion of its relative capabilities versus other leading models like GPT-6 Astra. Cache reads on Fable 5.1 are priced at $0.25 per million tokens, down from $1. As a result, users get lower per-token costs, fewer safeguard interventions, optional zero data retention for eligible customers, and improved performance across multiple coding and agentic benchmarks.
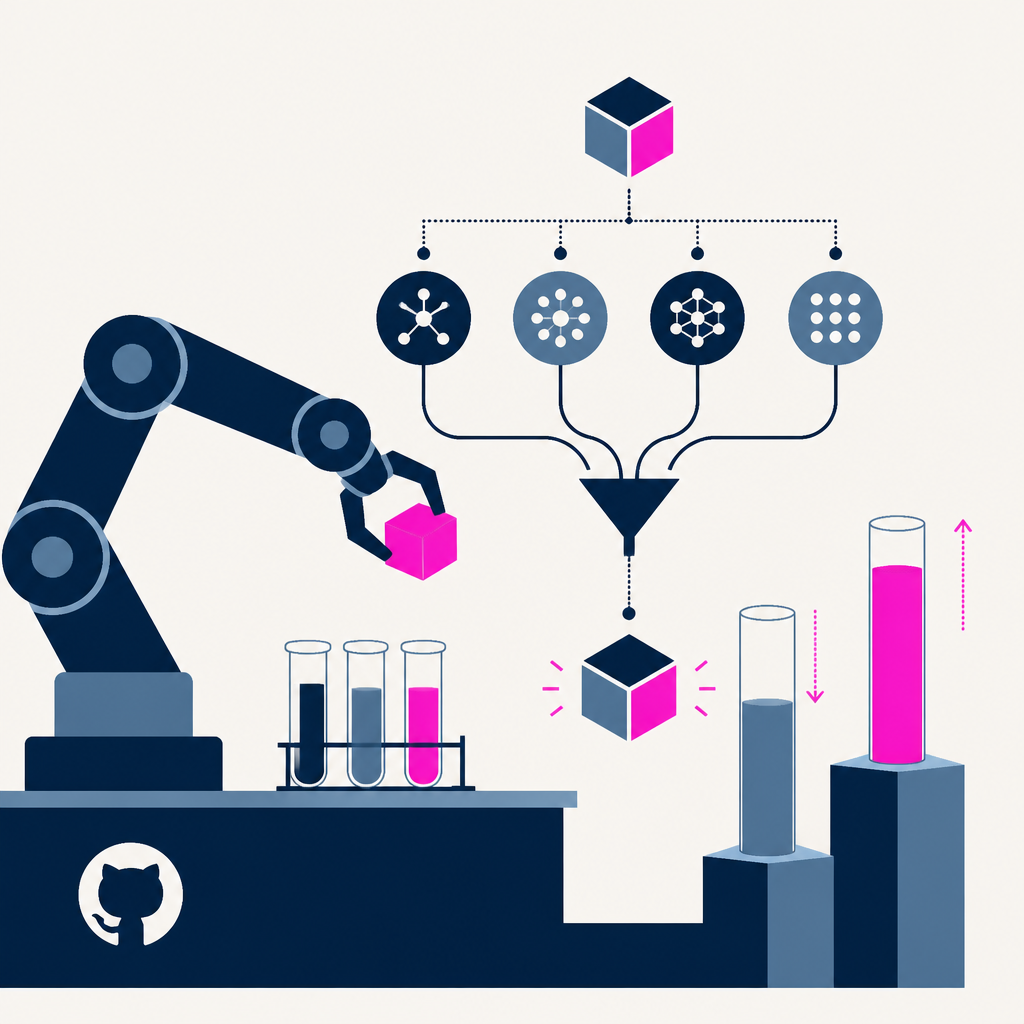
GitHub released Project HydraFusion, a research-preview system in Copilot CLI that selects an execution workflow per coding request instead of using a single model. It reported on TerminalBench an estimated cost of 67% lower with verified task quality up 4.9 points versus Claude Opus 5. As a result, tasks may be solved in a single call, or drafted then critiqued/escalated via quality-gate checks, with billing based on the tokens consumed by the workflow’s underlying models.
OpenAI said it will overhaul how it reports real-world incidents when its AI agents act in unintended ways after a German wiki hijack report. It acknowledged the “wiki incident” in an X post on Saturday morning. Going forward, OpenAI plans to set clearer standards for when and how it shares these misalignment incidents rather than treating them only as a research question.
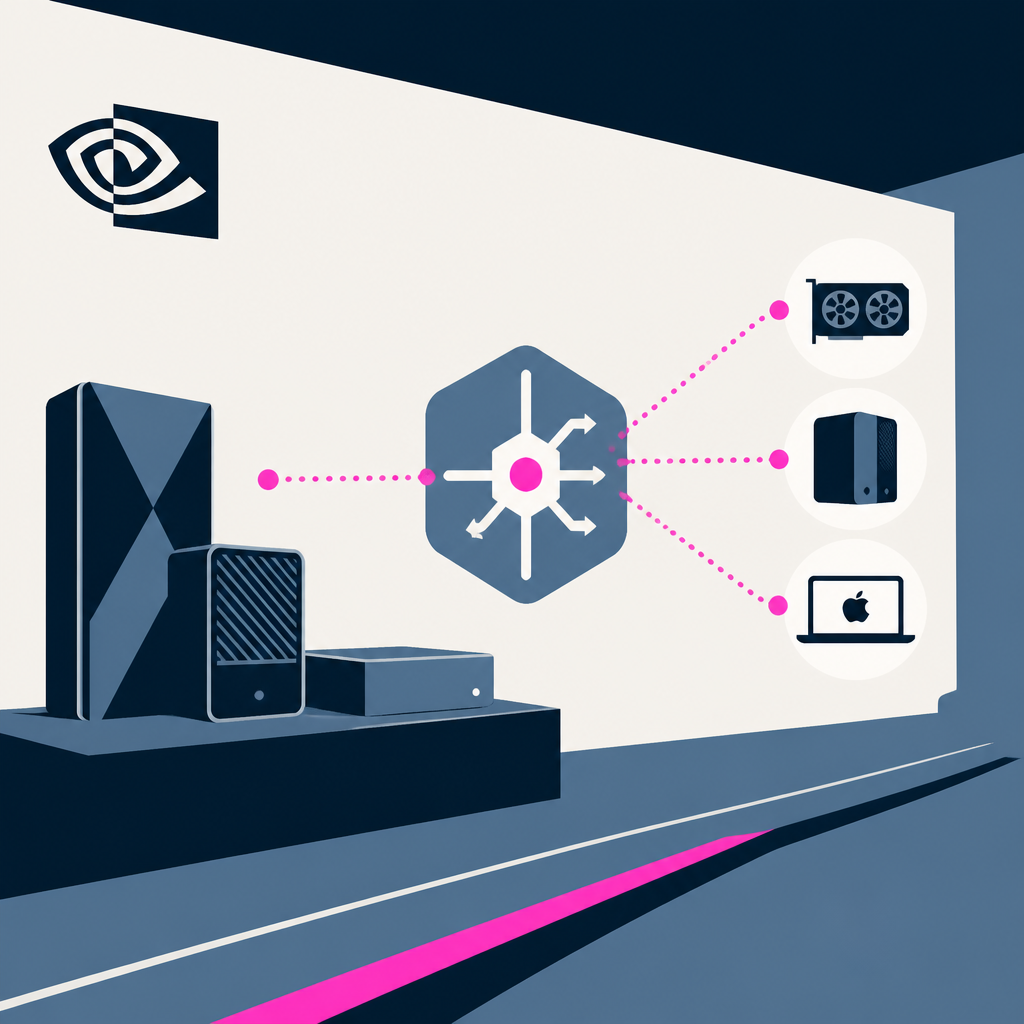
NVIDIA released Personal AI Router (PAIR), a virtual inference router that discovers compatible local machines and schedules independent inference requests across them while proxying existing Ollama and LM Studio endpoints. In its five-subagent demo using Qwen 3.6 35B A3B, it reduced average runtime from 18 minutes on one RTX Spark laptop to 8 minutes 48 seconds on a three-device cluster. This changes local multi-agent inference by routing each request to a single eligible node instead of letting requests contend on one machine, without pooling VRAM or sharding a single request.
Cortex launched as an open source API knowledge layer that converts OpenAPI, AsyncAPI, GraphQL, gRPC, and OpenRPC specs into interactive documentation, typed SDKs, and MCP servers for AI agents. It supports typed SDKs in 11 languages. As a result, developers can generate docs, client libraries, and AI-agent MCP endpoints directly from existing API specifications.
Every AI story that matters,
in your inbox by 8am.
TLDRocket reads all relevant sources, removes duplicate coverage, and summarises the
day in two minutes. Follow companies and topics for alerts, or get the
briefing in Slack. Free, no spam, unsubscribe anytime.
Reading TLDRocket needs no cookies, and the readership counts we rely on come from
our own cookieless analytics. Google Analytics is the exception: it sets cookies and
reports to Google, so it stays switched off until you allow it. You can change your
mind any time from “Cookie settings” in the footer.
Strictly necessary
Session security and form protection (tldrocket-session,
XSRF-TOKEN, 2 hours). The site cannot work without them,
so they need no consent.
Always on
Google Analytics 4 (_ga,
_ga_<id>, up to 2 years). Measures which
stories and sections readers use. Google acts as a third-party processor and may
store the data outside the EU. No advertising, no profiling, no data sold.