
TLDRocket
Sign in

Video Generation

133 summarised stories about Video Generation, each linking back to the original source. Browse all topics →

+ Follow this topic

Monday, 20 July 2026

At SIGGRAPH, NVIDIA Advances Graphics and Simulation With Agentic and Physical AI

NVIDIA 2 months ago 30 ● 4 sources

NVIDIA announced at SIGGRAPH multiple AI advances for creative and physical applications, including Model Context Protocol connections enabling AI agents within creative software like Blender and Unreal Engine, a Synthetic Video Detector NIM microservice for newsrooms achieving up to 92% accuracy on uncompressed video, and Cosmos 3 Edge, a 4-billion-parameter world model optimized for edge deployment on Jetson and RTX systems. The Synthetic Video Detector processes 1080p video in 22 milliseconds on RTX systems and 30 milliseconds on L40 GPUs, with partner Wowza deploying it across over 35,000 livestreaming deployments in 170 countries. These tools let creative professionals and physical AI systems run AI locally while maintaining control over data, reducing reliance on cloud services and enabling real-time inference for robotics, autonomous vehicles and infrastructure monitoring.
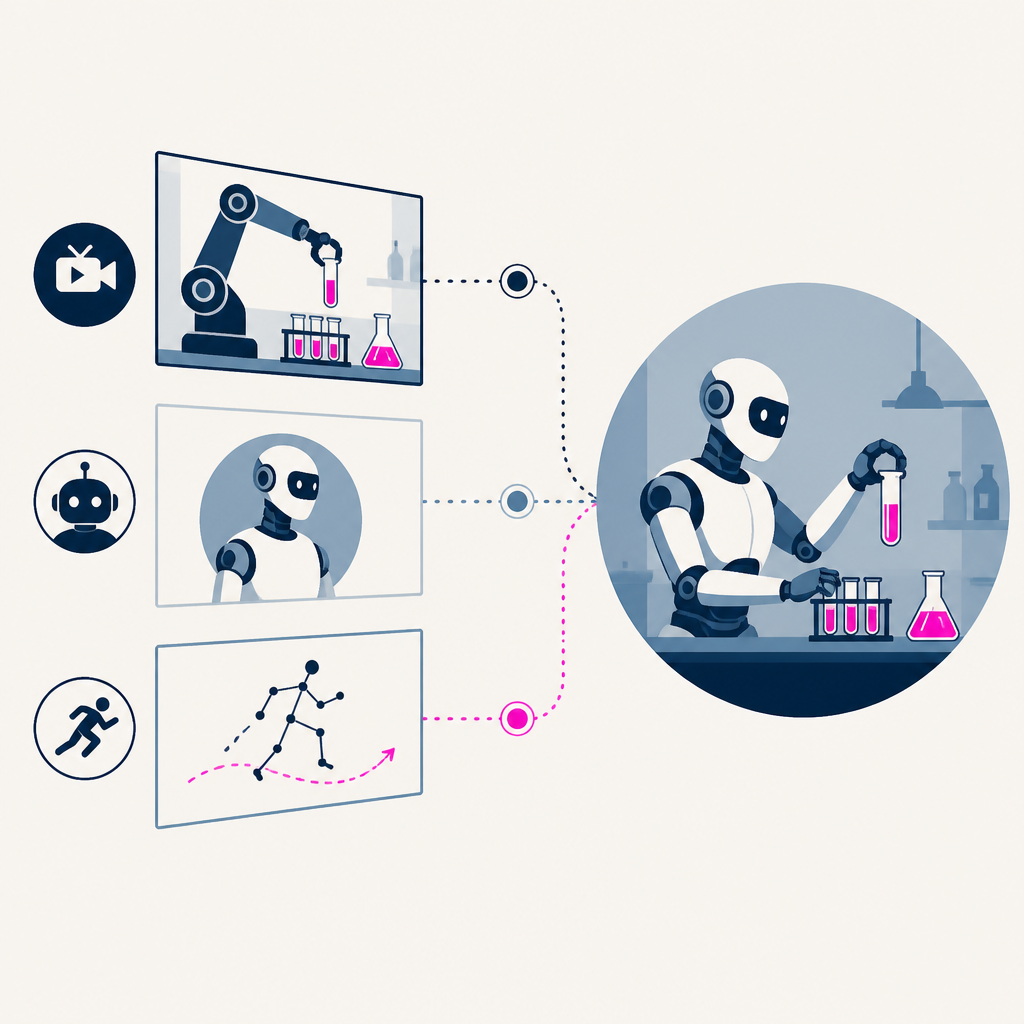
Prompt Mastery tutorial on directing AI video with layered shot technique

YouTube 2 months ago 17

A tutorial demonstrates a technique for improving AI-generated videos by layering multiple elements: using real footage as a motion reference, replacing the actor with an AI character, and applying motion transfer to maintain realistic movement synchronized with dialogue. The method involves three distinct steps performed sequentially on the video. This workflow allows creators to generate more natural-looking AI videos without manually keyframing movements.

LVSum: A Benchmark for Timestamp-Aware Long Video Summarization

Apple 2 months ago 29

Researchers introduced LVSum, a benchmark with 72 annotated videos averaging 16 minutes to evaluate how well multimodal large language models summarize long-form video content with temporal grounding. Testing showed that transcripts significantly outperform visual frames for summarization quality, with a substantial gap remaining between AI-generated and human summaries. Current MLLMs struggle with temporal grounding and cross-modal coherence, revealing systematic weaknesses in understanding the temporal sequencing of events in extended videos.

The daily briefing

Every AI story that matters, in your inbox by 8am.

TLDRocket reads all relevant sources, removes duplicate coverage, and summarises the day in two minutes. Follow companies and topics for alerts, or get the briefing in Slack. Free, no spam, unsubscribe anytime.