Simon Willison’s Weblog·1 month ago·
23
● 19 sources
The writer generated pelican-on-bicycle SVGs with GPT-6 Astra and compared them in a grid against GPT-5.6 Sol, Terra, and Luna across multiple reasoning levels. Astra used 16 input tokens versus 26 for Sol and Terra, and Astra was about twice Sol’s base rate ($10/million input and $50/million output vs $5/$30). The results show Astra producing consistently more detailed pelicans (though legs are still not always correct below max) while making tier-to-tier pricing less disparate due to lower token usage.
Zvi (Don't Worry About the Vase)·1 month ago·
48
● 6 sources
Claude Fable 5.1 and Mythos 5.1 system cards describe how Anthropic’s updated models change safety, cyber, alignment, and welfare results compared with prior releases. The bio benchmark LatchBio Bioinformatics improved from 72.5% to 77.6%, while alignment risk is reported as “low” rather than “very low” in the accompanying risk update. Overall, the update is presented as incremental with stronger cyber/classifier defenses and some modest capability gains, while retaining similar conclusions about CB-2 and autonomy risk.
OpenAI’s Astra scored very differently on ARC-AGI-3 depending on whether it was run through ARC Prize’s harness or OpenAI’s Provider Adapter. With the Provider Adapter, the unchanged GPT-6 Astra scored 98.6% and cost $17,332, versus 62.7% and $26,098 in ARC Prize’s standard harness. The result shifts attention from model selection to harness engineering because the surrounding software changes both score and cost.
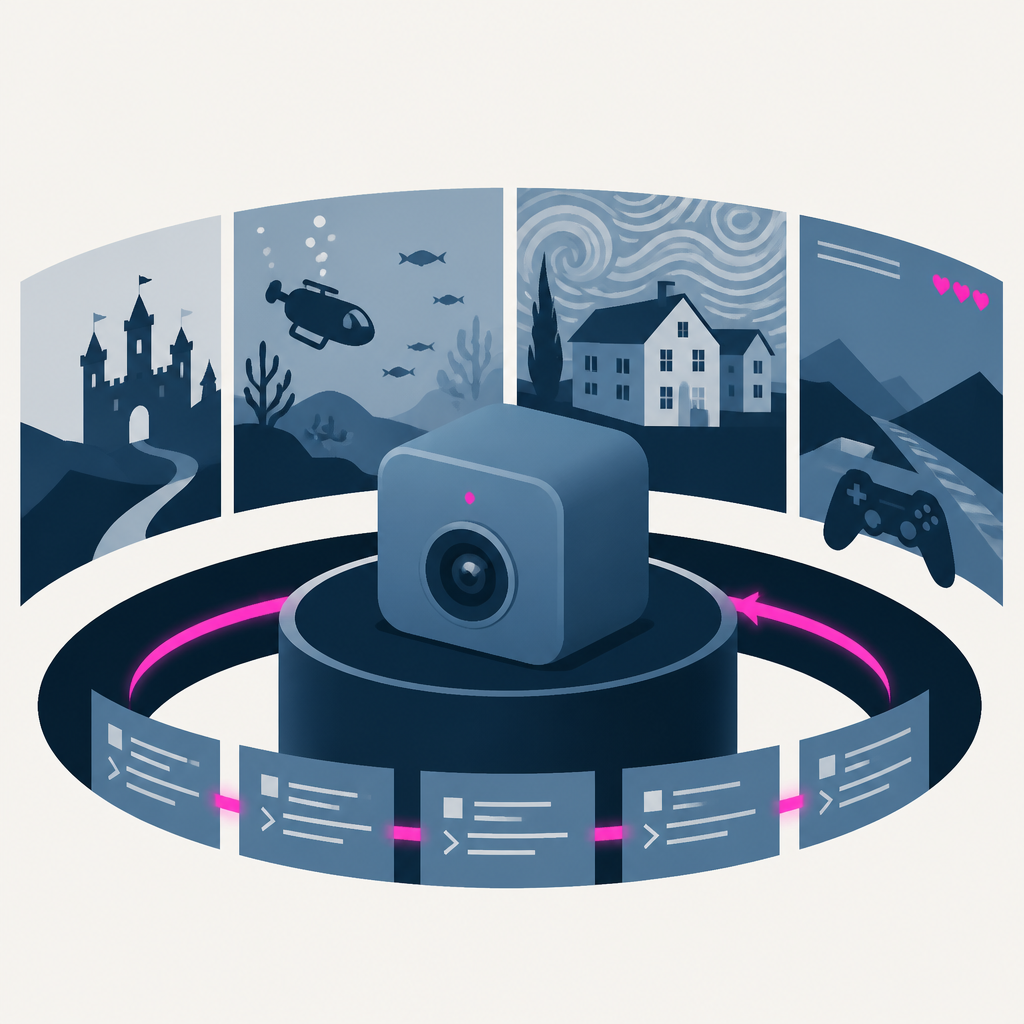
Arena AI ran Astra through a 3D “gauntlet” of scenes, including castles, underwater shots, Van Gogh’s house, and open-world games, and published the prompts.
OpenAI released GPT-6 Astra and says it reaches its Critical cybersecurity threshold while adding protections for harmful cyber actions. In a simulation using more than 54,000 internal Codex tasks, Astra got roughly half as many flags for higher-severity misaligned behavior as GPT-5.6 Sol. However, OpenAI reports Astra’s chain-of-thought monitoring is less effective under adversarial pressure, prompting a continued focus on auditing beyond CoT checks.
OpenAI’s GPT-6 Astra tested on ARC-AGI-3 achieved state-of-the-art performance while solving levels by compacting and reusing internal representations. It scored 62.7% on ARC-AGI-3 Semi-Private for $26,098 under the Standard harness and 99.9% for $18,817 under the Provider Adapter harness. Reporting will now include both harness results on the ARC-AGI leaderboard, with Provider Adapter runs also improving speed and reducing total tokens.
Artificial Analysis reported GPT-6 Astra benchmark results showing it ties Fable 5 on its Coding Agent Index while changing token use and pricing relative to GPT-5.6 Sol. GPT-6 Astra’s input/output token prices were raised to $10/$50 per million from $4/$20 (a 2.5x increase). As a result, Astra is more token efficient and less costly per task in coding, but it is 75% more expensive per task in the Intelligence Index, alongside a drop in hallucination rate from 92% to 51% at max effort and mixed gains across other evaluations.
Every AI story that matters,
in your inbox by 8am.
TLDRocket reads all relevant sources, removes duplicate coverage, and summarises the
day in two minutes. Follow companies and topics for alerts, or get the
briefing in Slack. Free, no spam, unsubscribe anytime.
Reading TLDRocket needs no cookies, and the readership counts we rely on come from
our own cookieless analytics. Google Analytics is the exception: it sets cookies and
reports to Google, so it stays switched off until you allow it. You can change your
mind any time from “Cookie settings” in the footer.
Strictly necessary
Session security and form protection (tldrocket-session,
XSRF-TOKEN, 2 hours). The site cannot work without them,
so they need no consent.
Always on
Google Analytics 4 (_ga,
_ga_<id>, up to 2 years). Measures which
stories and sections readers use. Google acts as a third-party processor and may
store the data outside the EU. No advertising, no profiling, no data sold.