The State of WebMCP
Spronta
WebMCP lets websites hand AI agents ready-made functions instead of making them click around blindly. Chrome's testing it now, but basically zero sites use it and no major AI agent calls it yet.
Based on reporting by Spronta — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
WebMCP is one of those standards that has everything lined up except the one thing that matters: actual use. Google and Microsoft engineers co-edit the spec, Chrome is running a live origin trial through version 156, Lighthouse already has an audit category waiting for it, and the draft was updated just two days before this was written. And yet almost no real website has deployed it, and not a single mainstream AI agent — not Claude, not ChatGPT, not Gemini itself yet — actually calls these tools in production.
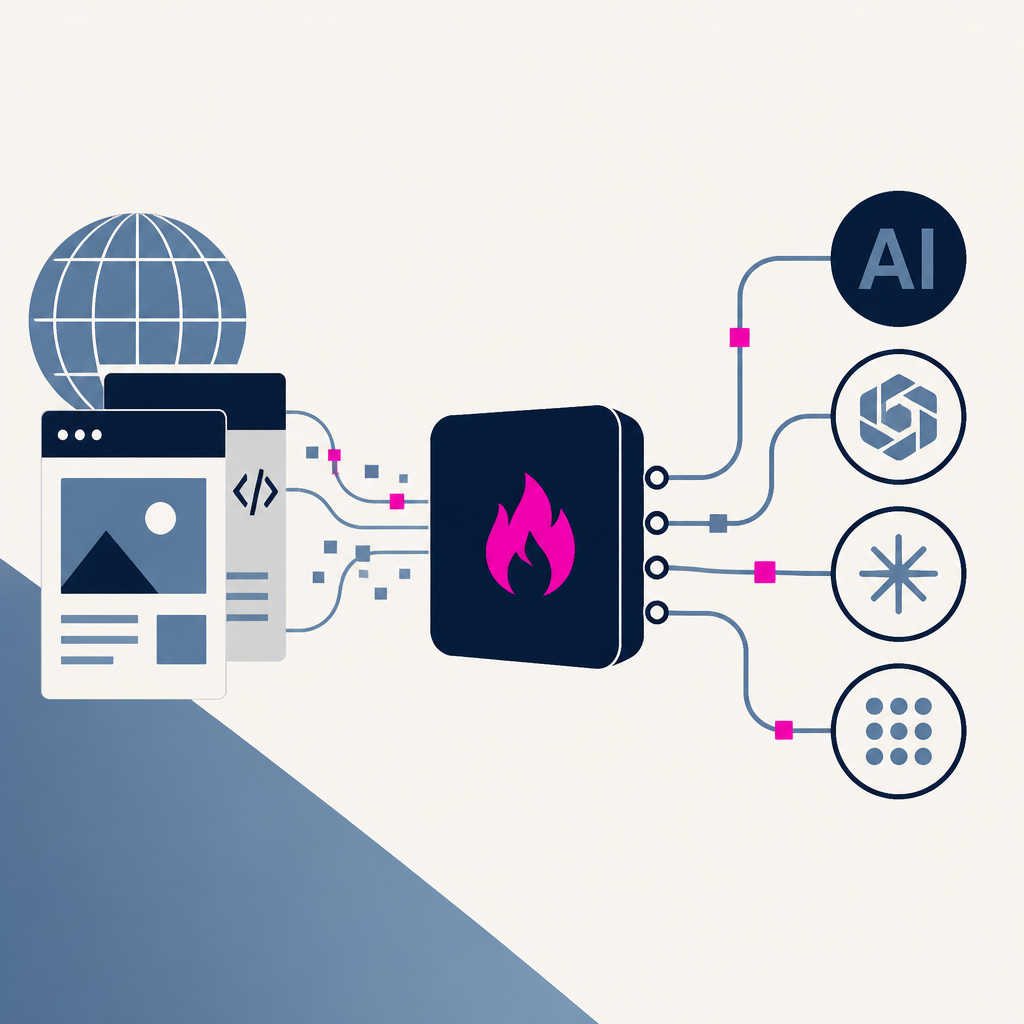
The idea is simple enough. Right now, an AI agent trying to use a website has to either scrape the page's DOM and guess what buttons do, or take screenshots and click on pixel coordinates. Both approaches are slow and break the moment a site gets redesigned. WebMCP flips that: a page registers named JavaScript functions with schemas, the browser exposes them to whatever agent is driving, and the agent just calls them directly. Tools run inside the page with the user's actual logged-in session, which is exactly what makes them useful and exactly what makes them risky.
The project traces back to Alex Nahas's 2025 open-source MCP-B experiment, then went institutional on August 28, 2025, when Microsoft's Patrick Brosset proposed it formally with Google co-authoring soon after. Since then things moved fast by browser-standards timelines — a W3C draft in February, an origin trial announced at Google I/O in May, Edge shipping experimental support behind a flag in June, and a spec change on July 21 that moved the API from navigator.modelContext to document.modelContext, with Chrome 150 already deprecating the old path.
But the demand side just isn't there. Google says Gemini in Chrome will be the first mainstream agent to consume these tools, though there's no ship date. Meanwhile companies like Expedia, Shopify, Booking.com and Target are listed as origin-trial participants, which signals intent more than deployment — actual measured adoption across the web rounds to zero, outside demo sites and the checker tools built to validate the spec. There are, notably, more third-party WebMCP checker extensions right now than there are real implementations.
Security is the part nobody's talking about loudly enough. Because tools execute with the user's session, a prompt-injected agent could call a perfectly legitimate tool with real permissions attached — a confused-deputy problem dressed up in new syntax. The spec gates things with permissions policies and a requestUserInteraction() confirmation step, but none of that stops a model that's been tricked by malicious page content from doing something it shouldn't. Anyone shipping tools now should treat each one like a public API endpoint: narrow scope, mandatory confirmation on anything with side effects, and logging on every call.
Everything points to the whole thing hinging on one company's internal roadmap. Google controls both the browser running the trial and the agent expected to consume the tools, so this isn't really a two-sided coordination problem in the usual sense — it's a scheduling problem inside Google. If Gemini in Chrome ships this year, WebMCP could go from zero adoption to Chrome stable within a couple of release cycles. If it slips into 2027, this joins the pile of browser APIs that arrived years before anyone needed them.
My take — AI-written commentary, not fact-checked reporting
I'll say the unfashionable thing: this is a well-designed standard suffering from an entirely predictable chicken-and-egg problem, and pretending otherwise with checker extensions and Lighthouse audits for a feature nobody's shipped is a bit theater-of-readiness. That said, when one company owns both the browser and the agent that's supposed to use it, betting against it feels foolish — Google doesn't need the market to coordinate, it just needs to finish its own roadmap. Worth building the boring readability and structured-data layers now regardless, because that work pays off whether or not WebMCP itself ever leaves the trial phase.
Read more about this at: Spronta