Ox Alpha, a free frontier-class AI coding model on OpenRouter, appeared on Aug. 20 with no identified developer and uncertainty over where users’ prompts and code go. Its context window supports 1,048,576 tokens (with 131,072-token output limits). As usage expands and third-party fingerprinting can only match parts of the serving stack, users cannot reliably verify identity or code retention, while reported token traffic has continued at scale.
Real-time AI deployments struggle in production when data pipeline and infrastructure bottlenecks—not model logic—drive issues like latency spikes and accuracy drops. Tim’s financial trading app reached about 740K operations per second when P99 latency rose to 3 seconds. To avoid the resulting doom loop, teams should monitor freshness and index health, separate workloads and vector indexing, and plan for retraining with controlled rollouts.
FreeToken was introduced as an edge-native Mixture-of-Experts serving engine that runs open-weight frontier models on a single workstation instead of requiring a datacenter GPU cluster. It reports GLM-5.2 at 753B parameters running at 14.9 tokens per second on a single RTX PRO 6000. The release adds Apache-2.0 code and deploy targets (including an OpenAI-/Anthropic-compatible endpoint and one-click desktop app), making local, air-gapped inference for solo developers and small teams more practical.
The page titled “Dropstone” presents an AI runtime described as one that can remember, learn, and act across environments.
No specific number, benchmark, or date is provided in the text shown.
As a result, there’s not enough information to determine any concrete technical change, release, or measurable impact beyond the general description.
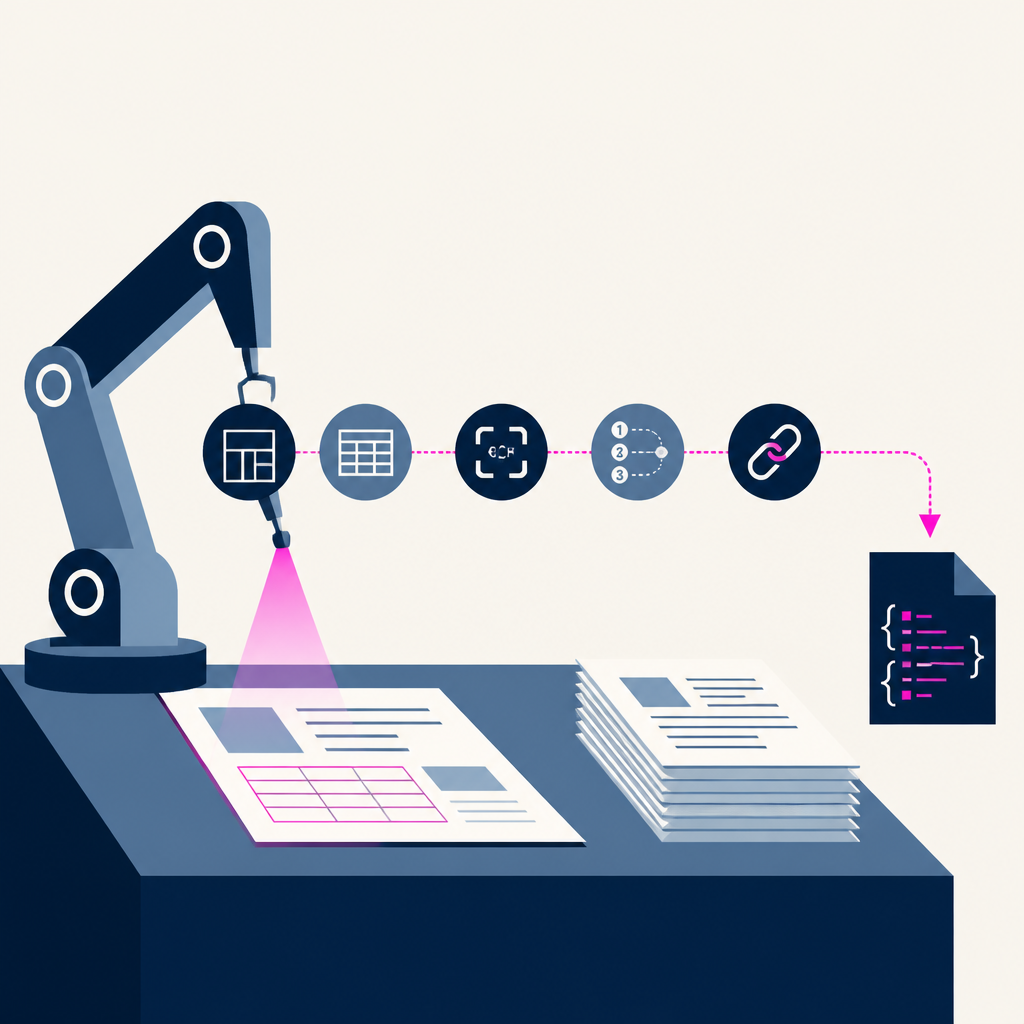
deepDoctection was used to build an end-to-end document intelligence pipeline that runs layout detection, table structure recognition, OCR, reading-order reconstruction, annotation linking, and structured JSONL export in one workflow. The tutorial targets deepDoctection version 1.2.x. It changes the output by producing Page objects plus page-level custom summaries (money mentions, date mentions, and a document “flavour” based on table coverage) that are then serialized for downstream retrieval/RAG use.
Every AI story that matters,
in your inbox by 8am.
TLDRocket reads all relevant sources, removes duplicate coverage, and summarises the
day in two minutes. Follow companies and topics for alerts, or get the
briefing in Slack. Free, no spam, unsubscribe anytime.
Reading TLDRocket needs no cookies, and the readership counts we rely on come from
our own cookieless analytics. Google Analytics is the exception: it sets cookies and
reports to Google, so it stays switched off until you allow it. You can change your
mind any time from “Cookie settings” in the footer.
Strictly necessary
Session security and form protection (tldrocket-session,
XSRF-TOKEN, 2 hours). The site cannot work without them,
so they need no consent.
Always on
Google Analytics 4 (_ga,
_ga_<id>, up to 2 years). Measures which
stories and sections readers use. Google acts as a third-party processor and may
store the data outside the EU. No advertising, no profiling, no data sold.