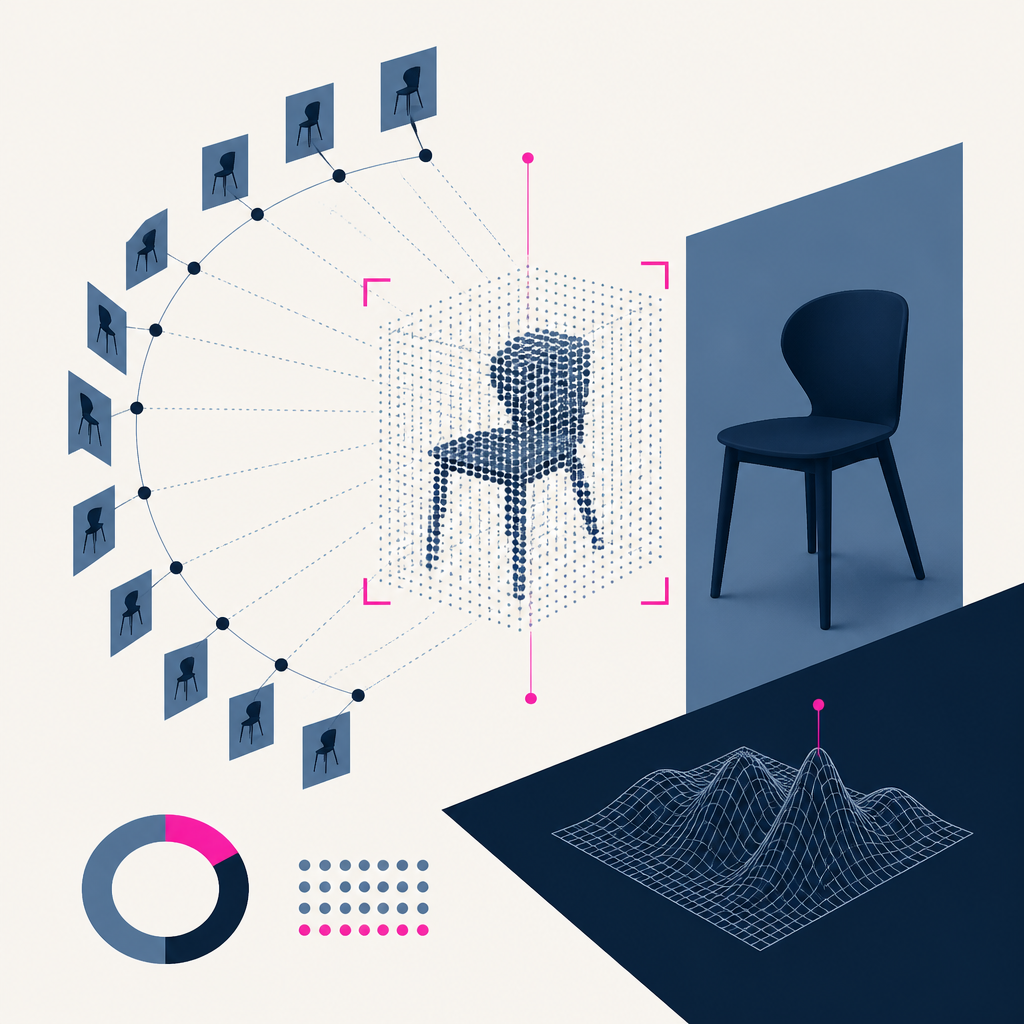
A tutorial built an end-to-end hierarchical NeRF in JAX using Flax, Optax, and jax3d’s volume-rendering primitives, including synthetic multi-view data generation and evaluation with PSNR and marching-cubes extraction. The configuration uses 24 training views at 64x64 resolution. The result is a trainable pipeline that performs novel-view synthesis and 3D reconstruction by combining coarse and fine networks with hierarchical importance sampling in volume rendering.
nftechie published a GitHub repository for a frozen-language-model setup using the MaleCNS v1.0 fly connectome and a separately trainable readout adapter. It retains 166,700 nodes and 25,582,938 directed connections while the adapter has 278,528 parameters and the adapter-only training updates next-token scoring. The project changes usage by enabling fully local training and chat via provided Python scripts (no API key or hosted inference) and saving outputs to runs directories without overwriting completed runs.
A fruit-fly brain connectome was trained to play Beat Saber using replay data and reinforcement learning. The training specifically uses replay signals so movements that score well are reinforced. The next training stage aims to reduce reliance on replays so the brain model can react on its own.
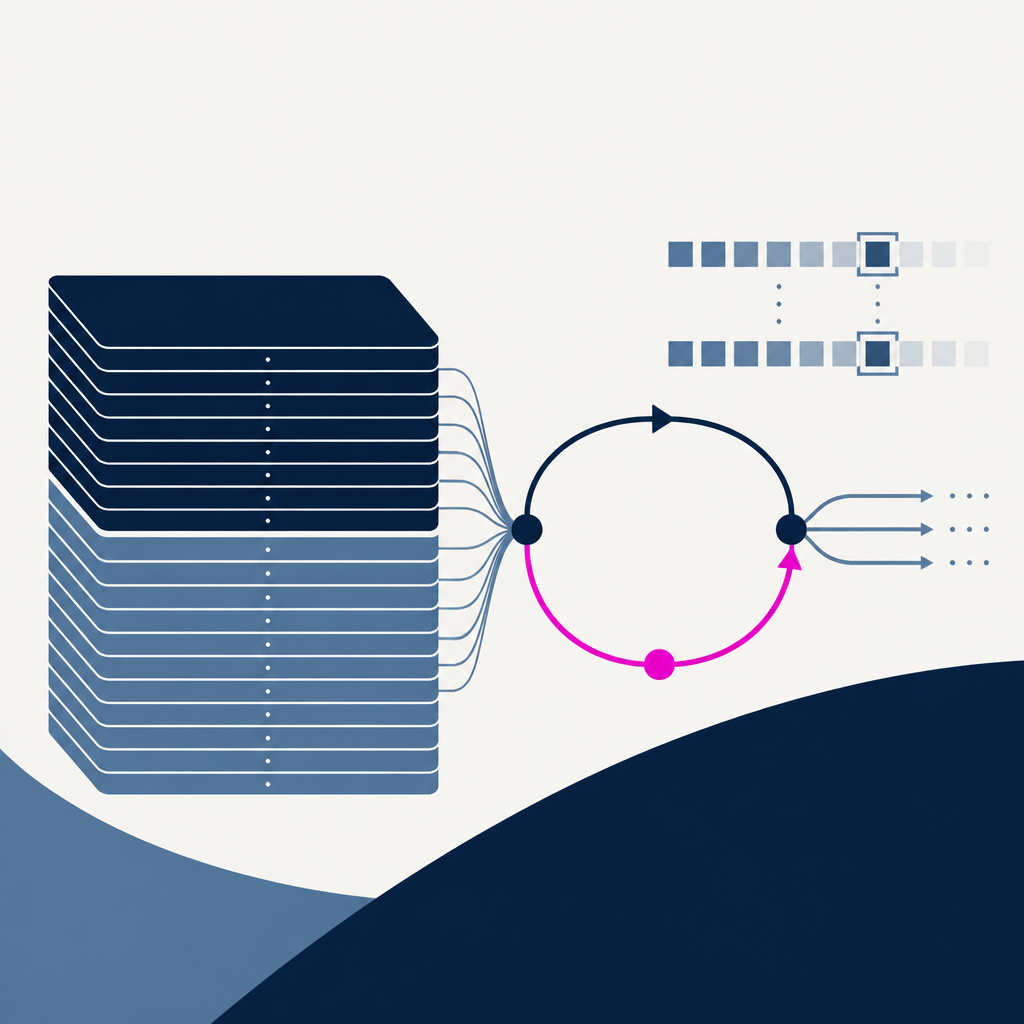
Yifan Zhang at Princeton proposes a Recurrent Looped Transformer (RLT) that carries the decoder’s final hidden state and layerwise sliding-window attention cache from token t into the next token t+1, with no reset at the prompt–response boundary. The reference design uses 48 encoder and 48 decoder layers, yielding 96 logical blocks per token and a state path depth of 48t after t tokens. The write-up provides an architecture and training/serving specification but reports no measured efficiency, reasoning quality, or scaling results, leaving those validation questions open.
Every AI story that matters,
in your inbox by 8am.
TLDRocket reads all relevant sources, removes duplicate coverage, and summarises the
day in two minutes. Follow companies and topics for alerts, or get the
briefing in Slack. Free, no spam, unsubscribe anytime.
Reading TLDRocket needs no cookies, and the readership counts we rely on come from
our own cookieless analytics. Google Analytics is the exception: it sets cookies and
reports to Google, so it stays switched off until you allow it. You can change your
mind any time from “Cookie settings” in the footer.
Strictly necessary
Session security and form protection (tldrocket-session,
XSRF-TOKEN, 2 hours). The site cannot work without them,
so they need no consent.
Always on
Google Analytics 4 (_ga,
_ga_<id>, up to 2 years). Measures which
stories and sections readers use. Google acts as a third-party processor and may
store the data outside the EU. No advertising, no profiling, no data sold.