
Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction
MarkTechPost 2 months ago 18 ● 3 sources
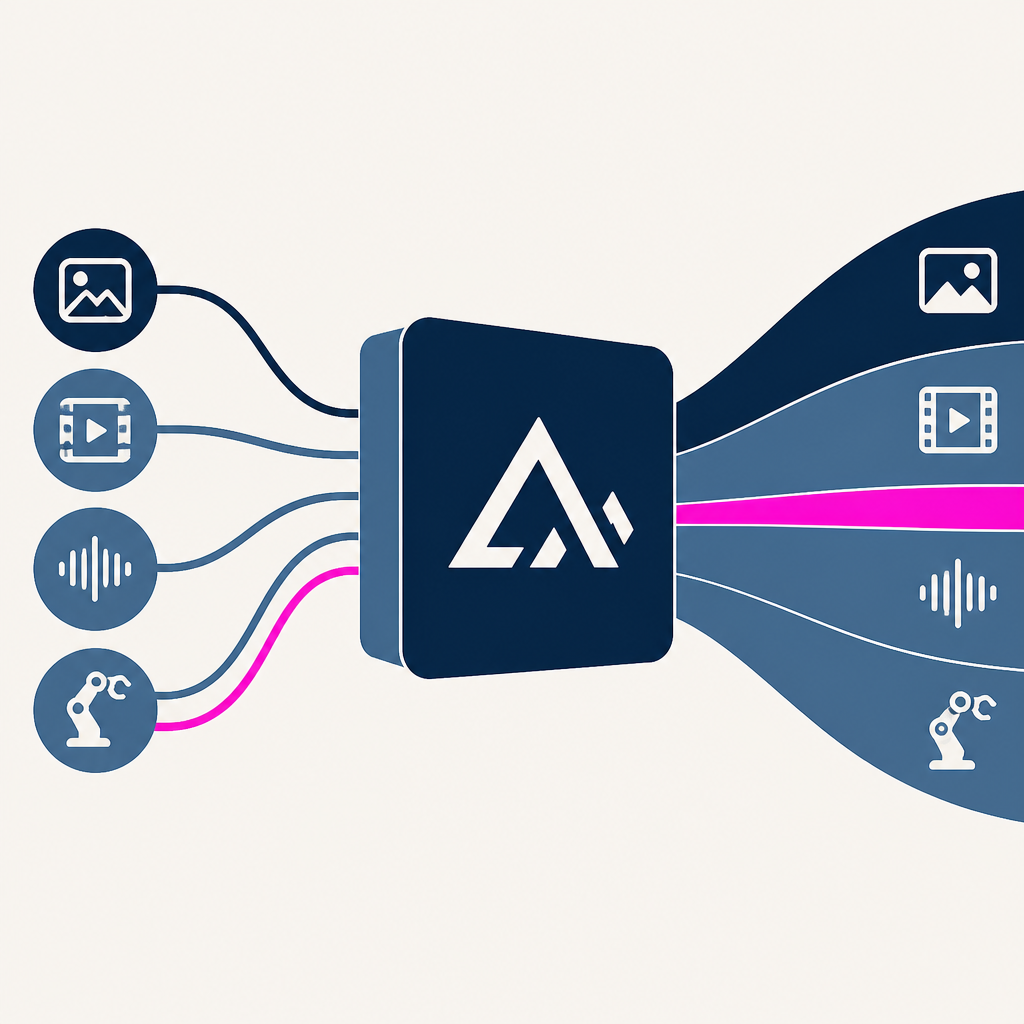
Black Forest Labs released FLUX 3, a multimodal foundation model that generates images, videos, audio, and robot action predictions using a single set of weights trained on all modalities simultaneously. FLUX 3 Video generates clips up to 20 seconds long with native audio and was preferred over Luma Ray 3.2 in 93% of comparisons in preliminary human evaluations at 720p resolution. The unified architecture means audio, motion, and spatial structure constrain each other during training, allowing the model to learn physical consistency across modalities.