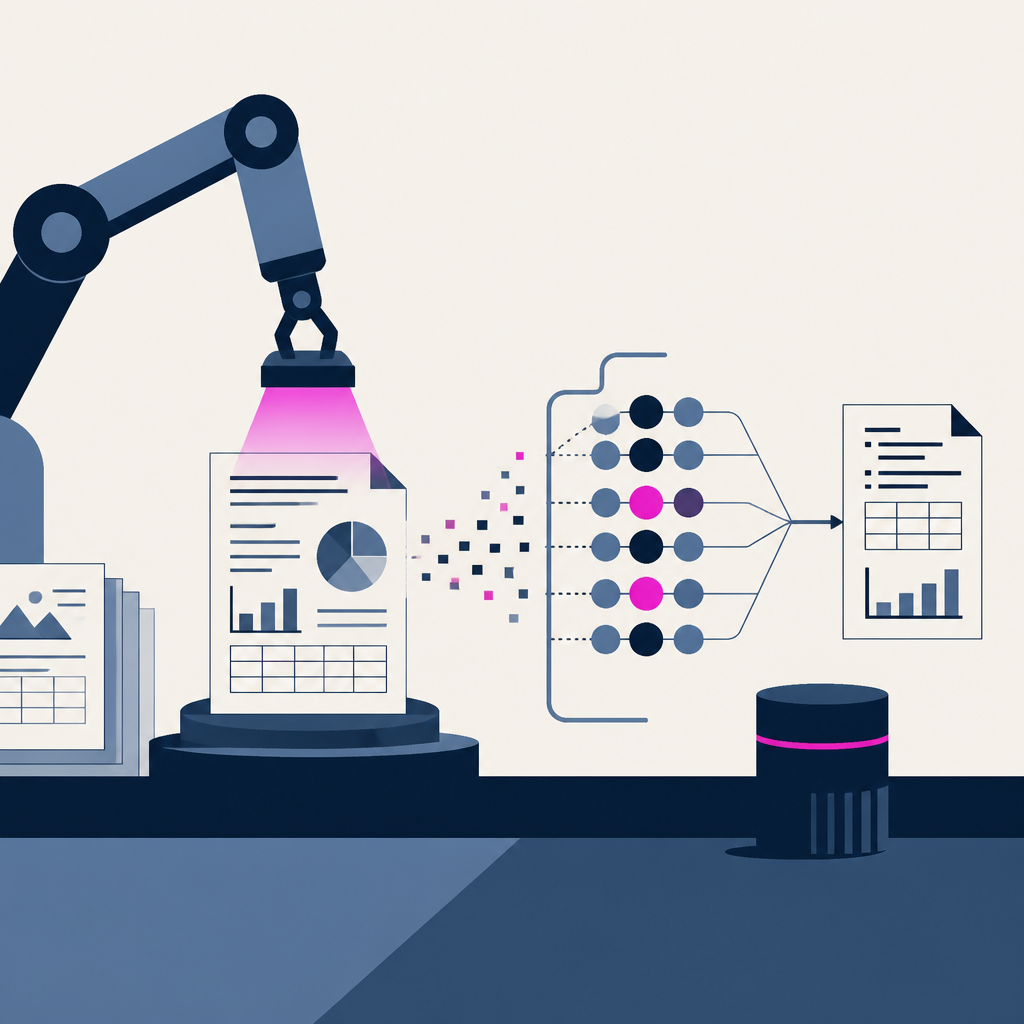
Jina AI released jina-ocr-v1, an end-to-end visual document parser that converts PDFs, scans, tables, charts, and invoices into clean Markdown in one pass. The model has 3.4B total parameters, with about 570M decoder parameters active per token, and it includes a speculative decoding head. The release adds deployable low-budget-GPU inference with lossless speculative decoding speedups (e.g., 1.95x tokens/sec on an NVIDIA L4) and distributes open weights under a CC BY-NC 4.0 license that restricts commercial use.
CoreWeave is preparing a user conference called Fully Connected while describing services and infrastructure aimed at cutting the cost and effort needed to deploy AI at production scale. CoreWeave says its autonomous improvement for AI agents can reduce costs by over 40% and speed up training by about 1.4 times without loss in quality. The event coverage and interviews are expected to focus on how CoreWeave and its partners tackle operational challenges like validation, reliability, and observability for increasingly complex AI models.
The article says AI agents can review pull requests quickly in testing but slower in production because the execution environment changes while the agent logic stays the same. It points to p99 latency increasing first when infrastructure is provisioned for average load rather than the bursty peaks created when tool results return. As a result, teams need agent-specific infrastructure that handles long step chains reliably and scales for bursty, sequential workflows to keep latency and costs predictable.
Every AI story that matters,
in your inbox by 8am.
TLDRocket reads all relevant sources, removes duplicate coverage, and summarises the
day in two minutes. Follow companies and topics for alerts, or get the
briefing in Slack. Free, no spam, unsubscribe anytime.
Reading TLDRocket needs no cookies, and the readership counts we rely on come from
our own cookieless analytics. Google Analytics is the exception: it sets cookies and
reports to Google, so it stays switched off until you allow it. You can change your
mind any time from “Cookie settings” in the footer.
Strictly necessary
Session security and form protection (tldrocket-session,
XSRF-TOKEN, 2 hours). The site cannot work without them,
so they need no consent.
Always on
Google Analytics 4 (_ga,
_ga_<id>, up to 2 years). Measures which
stories and sections readers use. Google acts as a third-party processor and may
store the data outside the EU. No advertising, no profiling, no data sold.