
vLLM
Tool ● Covered in 13 stories + Follow
vLLM is referenced as an inference serving tool/container used with GPU deployments and model-serving optimization features. In recent coverage, it is used alongside Amazon SageMaker and SageMaker HyperPod to reduce inference latency and cold starts (e.g., prefix-aware routing and model caching) and to improve KV cache reuse via LMCache and managed tiered KV cache with intelligent routing. vLLM is also integrated into training and rollout workflows (e.g., async GRPO with LoRA where adapter state is shared to vLLM replicas) and in guidance for serving large open-weight models via OpenAI-compatible endpoints.
Updated 18 September 2026
Latest developments
 OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device
MarkTechPost · 2 weeks ago ·
14
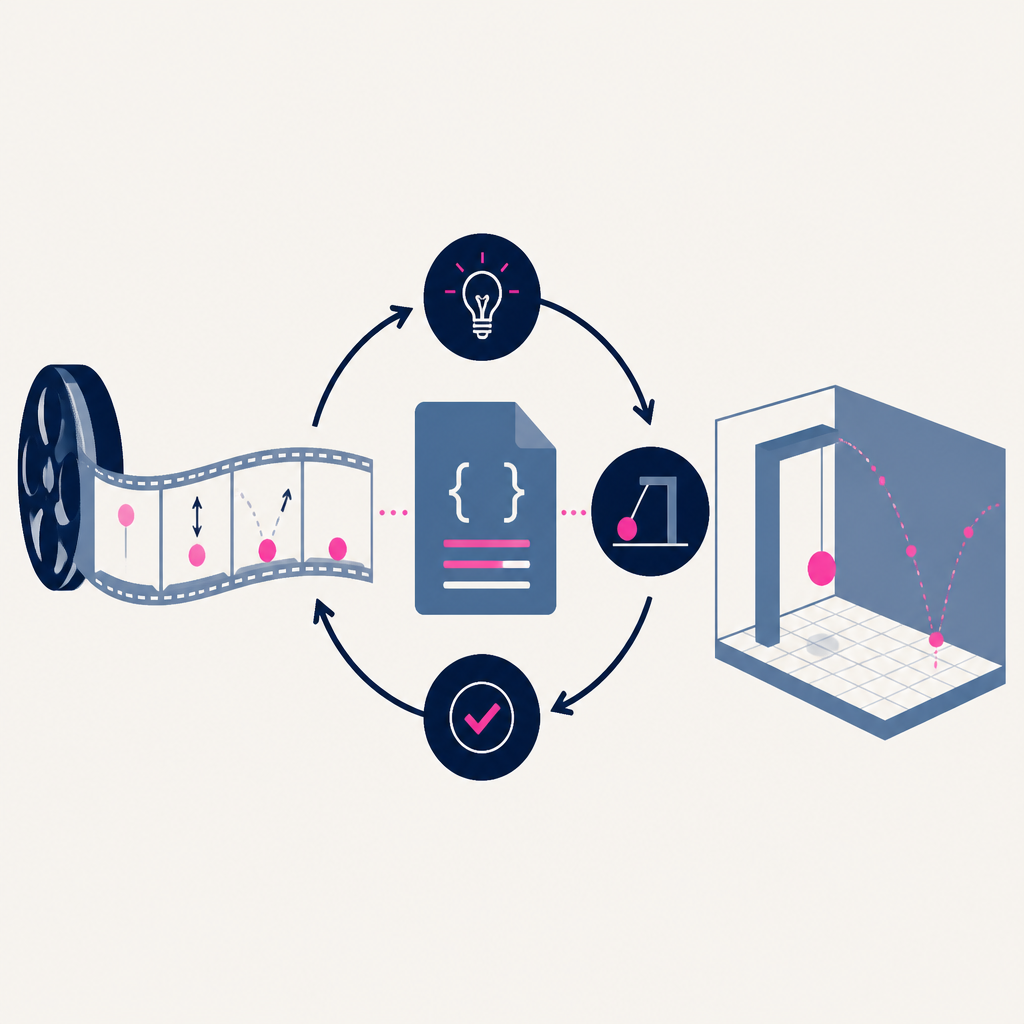 Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable MuJoCo Physics Programs
MarkTechPost · 3 weeks ago ·
33
Q3 2026
Meta released Muse Glimmer, an open-weights multimodal 30B model for local agentic and tool-using tasks under the Apache 2.0 license Open source release
Mistral AI releases Shieldstral, an open-source 3B-parameter multimodal safety classifier with policy-adaptive content moderation Open source release
AMD announces AI infrastructure strategy and partnerships at Advancing AI event Conference announcement
- Reduce LLM latency with prefix-aware routing on Amazon SageMaker Inference
- Reduce inference cold starts on Amazon SageMaker HyperPod with model caching
- Async GRPO with LoRA across HF Jobs: a bucket, a proxy, and no NCCL
- Deploying Qwen3.8-2.4T-A95B on Amazon SageMaker HyperPod with vLLM
- Inside the Megakernel Serving Engine for North Mini Code
- What Makes Inference Nondeterministic?
- OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34 Benchmarks and Built to Run On Device
- Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable MuJoCo Physics Programs
- AllenAI Open Instruct Tulu 3 Post-Training with SFT, DPO, RLVR, GRPO, and Verifier-Based Evaluation
- Tiered KV cache for large LLMs on Amazon SageMaker HyperPod with Curvine
- Meta is back with Muse Glimmer: local, agentic, multimodal, and open source
- Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety Classifier Matching Models 7× Its Size
- AMD calls its shot, but the real race is engineering velocity
Relationships
Products & technology
- Integrated with LMCache · 1 source
- Integrated with Amazon SageMaker HyperPod · 1 source
- Meta integrated with this tool · 1 source
- AsyncGRPOTrainer integrated with this tool · 1 source
- Hugging Face integrated with this tool · 1 source
- MirroS integrated with this tool · 1 source
- MiniCPM5-2B integrated with this tool · 1 source
Competition
- Cohere competes with this tool · 1 source