
What is Decision 3.0? vLLM Semantic Router’s New Open Decision Models
MarkTechPost Michal Sutter ● Covered by 8 sources
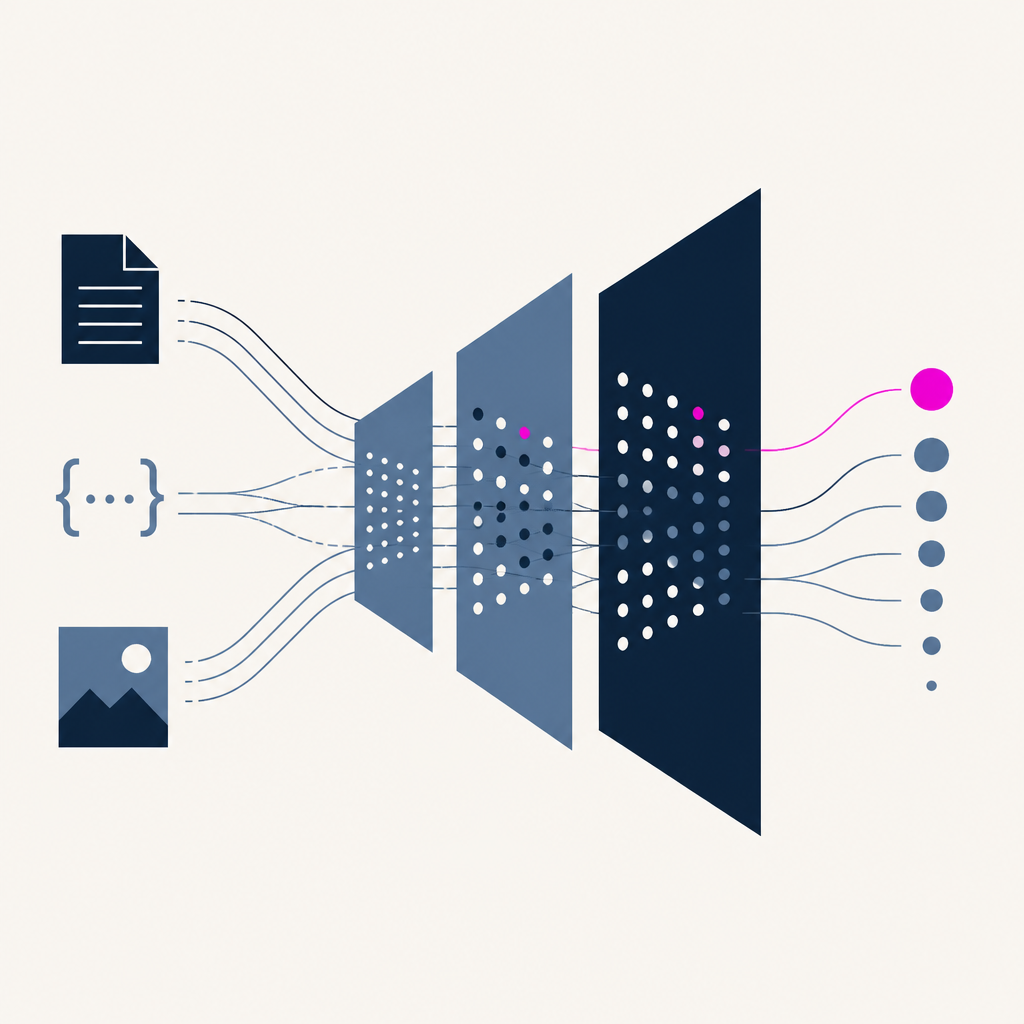
vLLM Semantic Router released Decision 3.0, a set of open multimodal decision models. They score text, JSON and images instead of generating replies, which makes routing and guardrails cleaner.
Based on reporting by MarkTechPost, Michal Sutter — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
vLLM Semantic Router has put out Decision 3.0, a family of open decision models under Apache-2.0. The lineup ranges from d3-lite at 0.85B parameters to d3 at 26.09B, and every model can take text, JSON and images. Instead of writing back a paragraph, the model returns probabilities for typed questions, so developers can use those scores to classify, route or block requests without scraping an LLM’s output.
That setup is the whole point. A request can include a state plus named questions, and each question can be a Choice, a Yes/No or a Score. The model answers all of them in one pass and returns probabilities for every option. vLLM Semantic Router calls that a “system one” pattern for routers and guardrails. The practical gain is obvious: fewer hacks, less parsing, and a cleaner thresholding step.
All five models are fine-tunes built on Qwen bases. The biggest one, d3, uses Qwen3.8-27B. The smaller four are based on Qwen3.5 checkpoints. Each size also includes a vision encoder, and the models can read several PNG, JPEG or WebP images at up to 1.6 megapixels each. The cards say median latency was measured on a single AMD Instinct MI325X GPU, with text latency ranging from 21.7 ms for d3-nano to 84 ms for d3.
On the team’s internal board, d3 leads both the text and vision tables with scores of 64.1 and 71.6. It also posts 97.7 on KIE document extraction and 97.3 on InfographicVQA, while weaker spots include 34.1 on R-Bench-M, 46.2 on MMMU-Pro vision and 44.6 on Hateful Memes moderation. The size story is maybe the most interesting part: d3-flash, at 9B, reaches 59.0 and beats Decision 2.0’s 27B score of 55.9 on the public suite. That is a neat little reminder that parameter counts still love to be rude to our assumptions.
My take — AI-written commentary, not fact-checked reporting
This is the kind of model release that actually helps people ship product instead of demo slides. Open, multimodal, probability-first routing is a much saner story than asking a chat model to cosplay as a classifier and then cleaning up its mess. The industry keeps treating “smart” as a synonym for “verbose”; Decision 3.0 picks the less glamorous but more useful lane.
Read more about this at: MarkTechPost
Related stories
 Fastino Releases GLiNER2.5-Decide: A 340M Open-Weight Decision Model That Runs on CPU
MarkTechPost · 2 weeks ago ·
40
 llm-openai-decisions 0.1a0
Simon Willison’s Weblog · 5 days ago ·
33
 AWS Strands Labs Releases Strands Decider 2B: An Open Source Decision Model That Picks Options in About 115 ms
MarkTechPost · 1 week ago ·
48