
Liquid AI Releases Open-Weight d1-3B and d1-omni-600M: Multimodal Decision Models With Zero Output Tokens
MarkTechPost Asif Razzaq ● Covered by 2 sources
Liquid AI released two open-weight d1 models that answer with probabilities, not text. That makes them fast for routing, moderation, and edge devices.
Based on reporting by MarkTechPost, Asif Razzaq — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
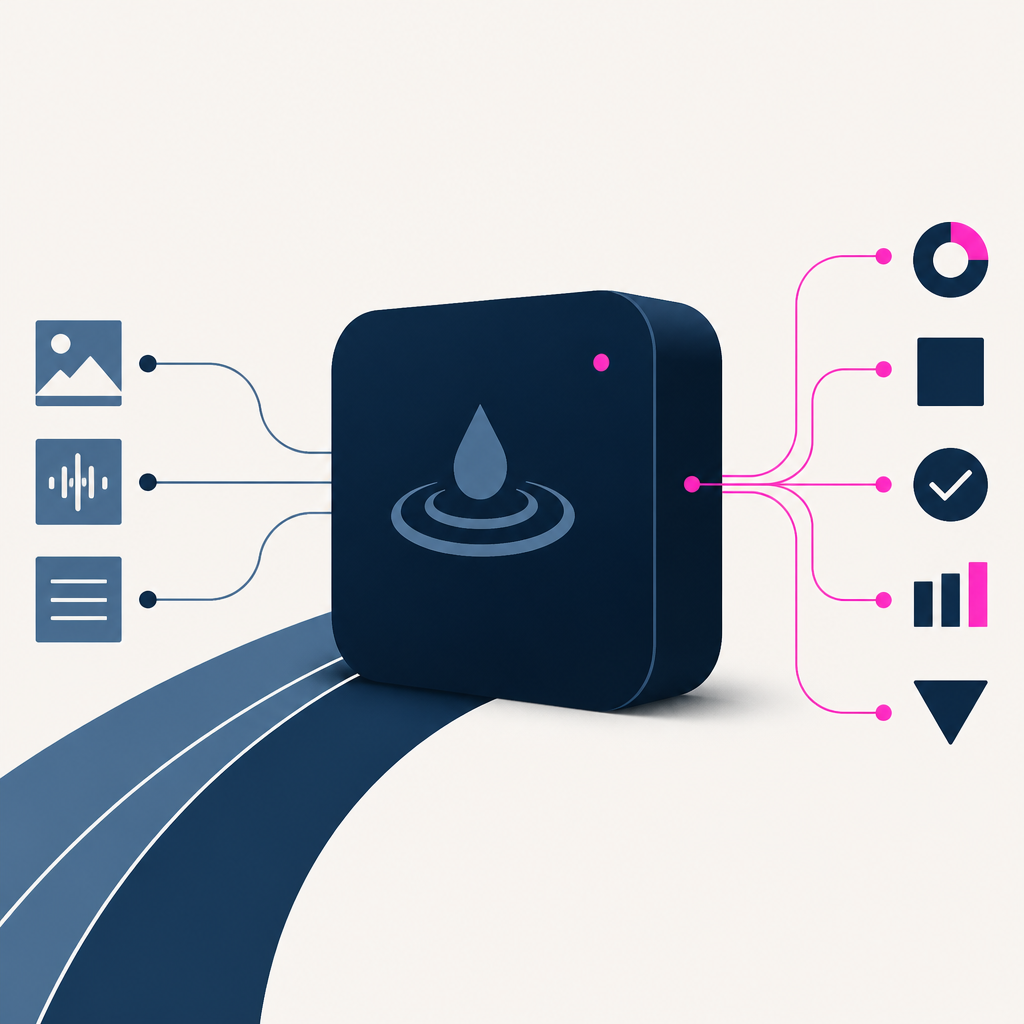
Liquid AI has put out Open d1, a pair of open-weight multimodal models built for decisions instead of prose. The larger one, d1-3B, reads text and images. The smaller d1-omni-600M handles text plus either an image or audio. Neither model generates text at all; each returns typed answers in one pass with output_tokens set to 0.
That design makes the pitch unusually practical. Liquid AI is aiming at real-time work on NVIDIA gear, from DGX servers to RTX workstations and Jetson boards. Both checkpoints are already on Hugging Face, they load through Transformers, and they have day-one support in llama.cpp. The license, LFM Open License v1.0, allows free commercial use under $10 million in annual revenue.
The models are not chatbots. Liquid AI frames them as decision systems that read a state and a set of named questions, then return probabilities for allowed answers. It defines three question types: noul for yes-or-no, choice for one label from named options, and score for an ordered rubric with 2 to 10 levels. Several questions can share one state in a single call, which is why the company points them at routing, moderation, intent classification, reranking, LLM-as-a-judge scoring, guardrails, and visual inspection.
The bigger model starts from LFM2.5-VL-3B and has 3.12 billion parameters. Liquid AI says it combined weights from LFM2.5-2.6B with that model’s text backbone, then fine-tuned several checkpoints with different seeds and data mixtures before merging them again. It uses a 400M SigLIP2 NaFlex vision encoder and a 32,768-token context. The smaller d1-omni-600M has 587 million parameters, a 16,384-token context, and a 17-layer FastConformer audio encoder. Audio requests are capped at 30 seconds, and a single request takes either images or audio, never both.
Performance is the part Liquid AI seems happiest to talk about. On Decision Index v0.2.1, d1-3B scores 48.57, which puts it ahead of every model under 10B in the source comparison and just behind Winnow-12B. Liquid AI also says it measured 8 ms for one question on an RTX 4090 with model.compile(mode="reduce-overhead"), and 16 ms without that setting. On Jetson AGX Thor, it reports 16 ms for one question and 20 ms for three questions over one state.
My take — AI-written commentary, not fact-checked reporting
This is the rare AI release that feels built for a job instead of a demo reel. The open-model crowd spends a lot of time pretending every problem wants chat; Liquid AI is betting that plenty of them want a clean probability and a quick answer. That is a saner pitch, and a slightly less exhausting one too.
Read more about this at: MarkTechPost
Related stories
 Liquid AI Releases d1: A Decision Model That Returns Calibrated Probabilities With Zero Output Tokens
MarkTechPost · 1 week ago ·
5
 Liquid AI Releases LFM2.5-2.6B: An On-Device Agentic Model With 128K Context, Tool Calling, And Open Weights
MarkTechPost · 2 months ago ·
50
Decision models are suddenly everywhere. OpenAI’s is now public.
The New Stack · 6 hours ago ·
16