Launch HN: Hebbian Robotics (YC S26) – Build scalable robotics data pipelines
GitHub kstonekuan
Hebbian Robotics launched HFlow, an open-source SDK for robotics data pipelines. It turns messy robot recordings into checked, queryable datasets instead of brittle scripts.
Based on reporting by GitHub, kstonekuan — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
Hebbian Robotics has launched HFlow, an SDK for turning robotics recordings into standardized, quality-checked episodes and dataset manifests. The project comes from Brandon and Kingston, who say they kept running into the same problem from different sides: robotics teams keep rebuilding the same data plumbing, and it eats time before model training even starts.
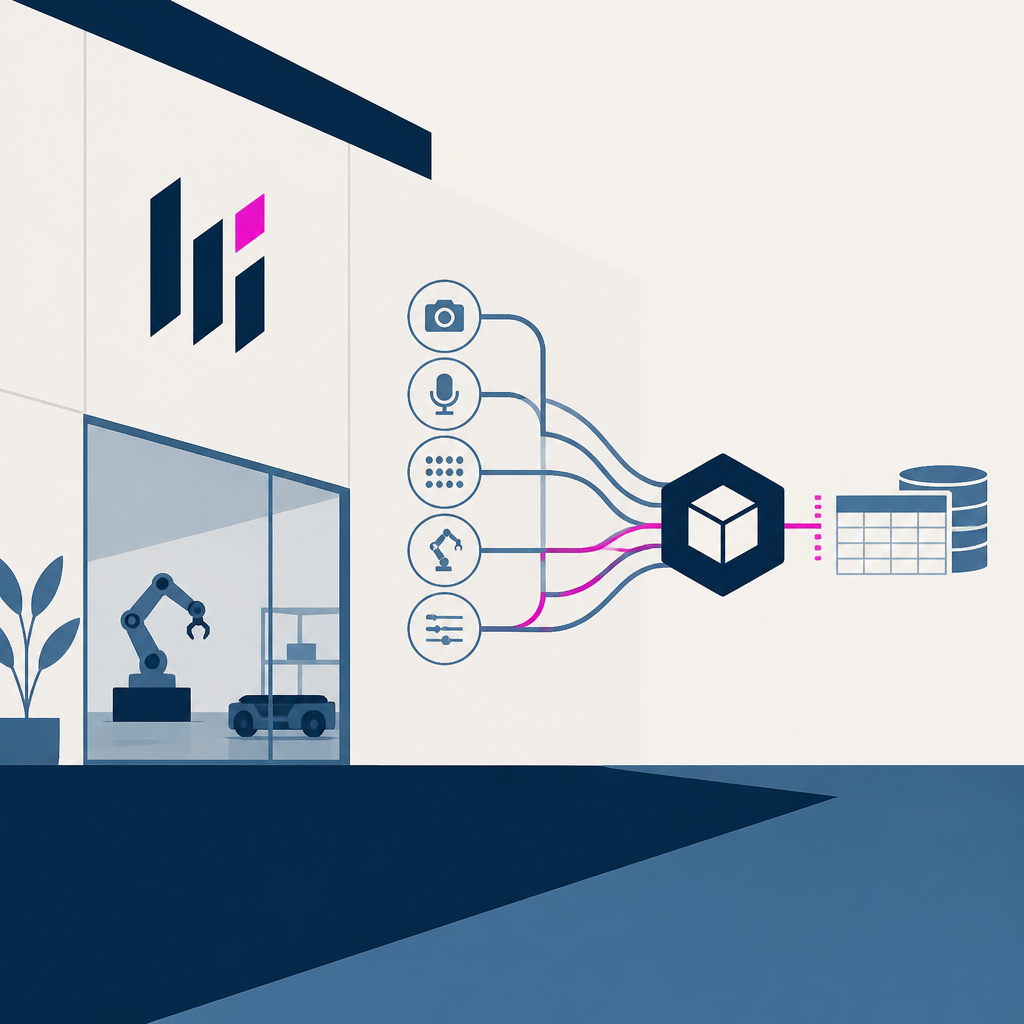
The pitch is simple. Robot data usually arrives as a tangle of synchronized video, joint states, actions, timestamps, and metadata. HFlow treats that bundle as one episode and processes it end to end. The founders say that matters because the first failures are often boring ones — frozen cameras, missing topics, timestamp drift, duplicate recordings — and those are exactly the kind that slip into training sets when the codebase is held together with scripts.
HFlow’s pipeline is built from plain Python functions that act on an episode and return measurements, artifacts, or transformed data. During development, those functions can run in-process. For scheduled processing, the same registered steps can be packaged as Airflow 3 DAGs, so teams can track task status, logs, retries, and reruns instead of guessing what happened after the fact.
Right now HFlow accepts one MCAP file per episode. The project leans on MCAP because it keeps timestamped multimodal streams aligned in one file, and because the output stays compatible with Foxglove and Rerun. HFlow writes a canonical MCAP with in-band H.264 video, grouped camera and state chunks, and provenance describing how the output was produced. It also records explicit behavior versions, plus links between catalog entries, the source episode, and the pipeline run.
The catalog side is where the product gets more opinionated. HFlow stores measurements, metadata, version stamps, and artifact locations in an append-only Parquet catalog, then lets teams query it with DuckDB SQL to create a version-pinned manifest without reopening the recordings. It can quarantine an episode when critical checks fail, but it does not delete data. The company’s point is that evidence and policy should be separate things.
Hebbian says HFlow is pre-v1 but already works end to end. It is free under Apache-2.0, and the current open-source deployment is a single-tenant workspace. The hosted multi-tenant control plane is not built yet, and the company is considering managed workspaces and enterprise support as the business model.
My take — AI-written commentary, not fact-checked reporting
This is the right kind of boring software: contracts, provenance, and fewer heroic scripts. Robotics has spent too long pretending data cleanup is a side quest, when it’s the whole game. Open source is the sane move here; if the pipeline breaks, the robots shouldn’t get to keep the secret.
Read more about this at: GitHub