Launch HN: Expanse (YC P26) – Unlock Wasted GPU Capacity
Hacker News ismaeel_bashir
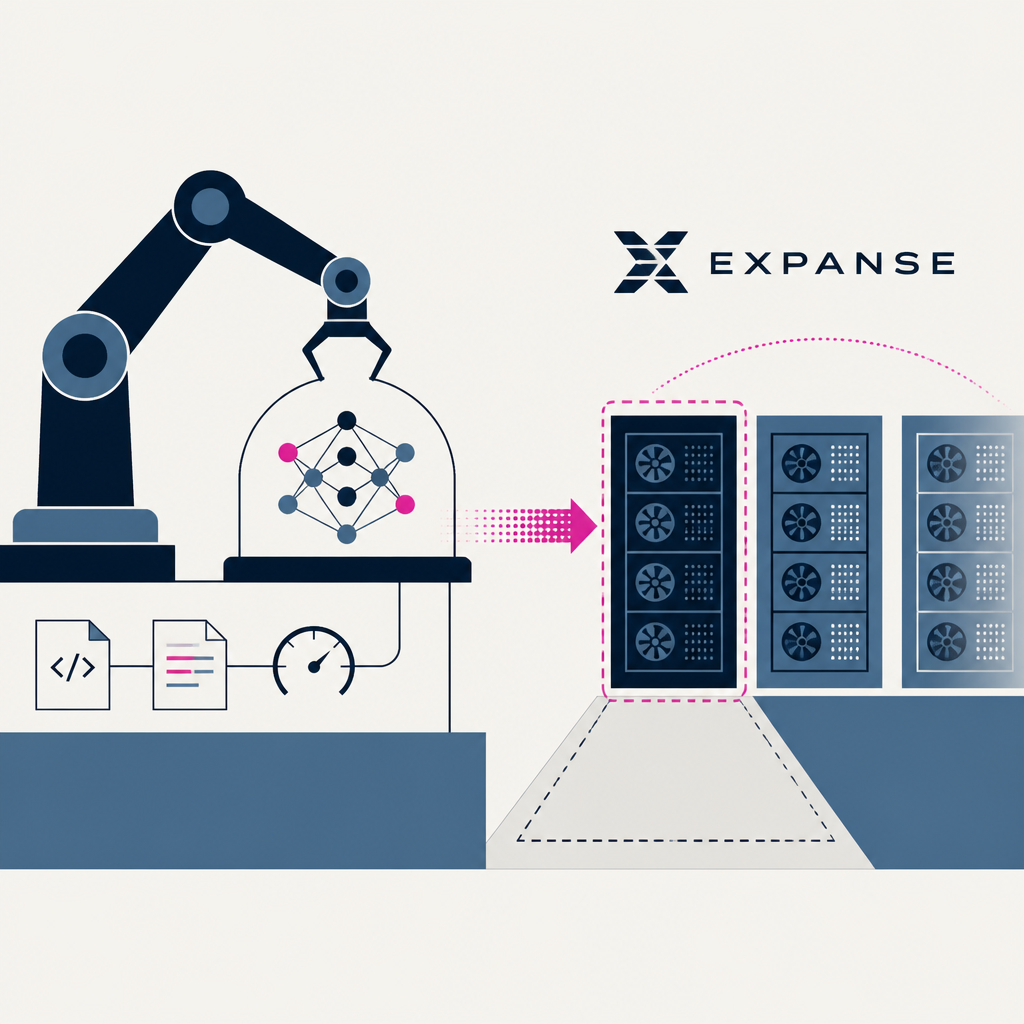
Expanse uses deep learning models that analyze source code, submission scripts, and hardware telemetry to predict actual GPU and compute resource needs before jobs run on HPC clusters, addressing the problem that datacenters waste 59% of compute due to users over-requesting resources by 2-3x to avoid job failures. The company measured a national-scale HPC cluster and found roughly $8.5 million in wasted compute monthly, and their multimodal predictor outperforms frontier LLMs by 8x on resource prediction tasks. Customers can recover wasted capacity and reduce over-provisioning, with Expanse offering paid pilot deployments starting with a two-week measurement window.
Why it matters
Hey HN, we’re Ismaeel, Eren, Yafet and Nikodem. We built Expanse (https://expanse.sh/) to increase the effective capacity of your HPC/GPU clusters running schedulers/orchestrators like Kubernetes and SLURM. We read the source code, job submission script, and the hardware a workload is about to run on to predict what the job actually needs before the cluster sees it. We also flag failures we think are about to happen and surface line-level optimisations the researcher can apply themselves.The problem: Datacenters run at roughly 30% to 40% effective utilisation. Users request more resources than what they actually need, because of asymmetric risk: while over-requesting is bad because it’s expensive and wastes capacity that someone else could have used, under-requesting kills your job mid-run and you lose days of work. So everyone over-requests by two to three times.We measured one national-scale HPC cluster for a month and from 122k jobs, 59% of the compute was wasted. At on-demand cloud