
Building an End-to-End Document Intelligence Pipeline with deepDoctection
MarkTechPost Sana Hassan
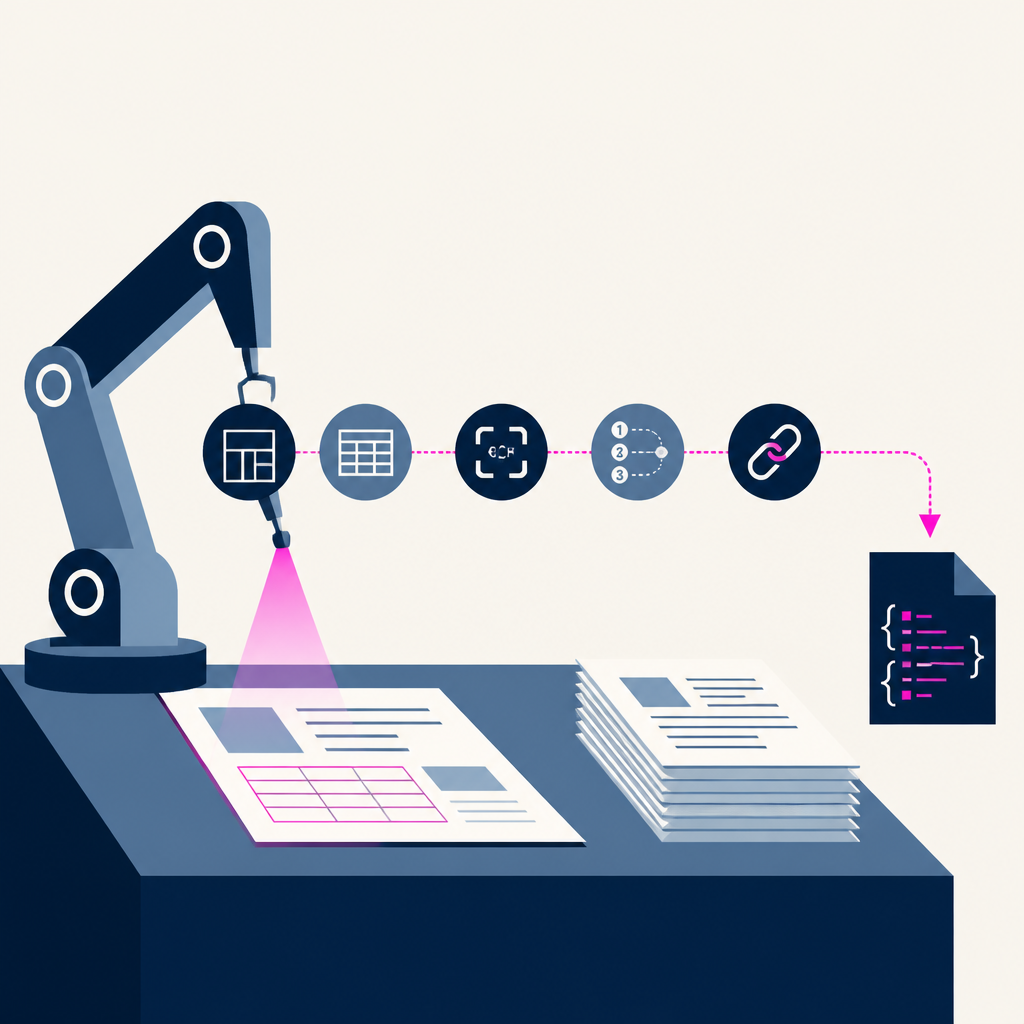
deepDoctection was used to build an end-to-end document intelligence pipeline that runs layout detection, table structure recognition, OCR, reading-order reconstruction, annotation linking, and structured JSONL export in one workflow. The tutorial targets deepDoctection version 1.2.x. It changes the output by producing Page objects plus page-level custom summaries (money mentions, date mentions, and a document “flavour” based on table coverage) that are then serialized for downstream retrieval/RAG use.
Why it matters
Build an end-to-end document intelligence pipeline with deepDoctection. This tutorial covers configuring layout analysis, DocTR OCR, and table extraction, while demonstrating how to implement custom services for entity recognition and generate structured JSONL data for your RAG workflows. The post Building an End-to-End Document Intelligence Pipeline with deepDoctection appeared first on MarkTechPost.
Related stories
 Developing an End-to-End Document Intelligence Pipeline with docTR for OCR, Layout Analysis, KIE, Benchmarking, and Searchable PDFs
MarkTechPost · 1 month ago ·
39
 How to Build an End-to-End OCR Pipeline with Baidu’s Unlimited-OCR for High-Resolution Images and Multi-Page PDF Parsing
MarkTechPost · 1 month ago ·
25
 Building a Multimodal RAG Pipeline with NVIDIA NeMo Retriever, Hosted NIMs, LanceDB, Reranking, and Grounded Generation
MarkTechPost · 1 month ago ·
41