20 Agentic Use Cases of TypeSafe AI’s Jev
MarkTechPost Asif Razzaq
TypeSafe AI launched Jev, a model that doesn’t chat or code — it makes typed decisions instead. It’s built for the tiny yes/no calls that agent loops keep making all day.
Based on reporting by MarkTechPost, Asif Razzaq — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
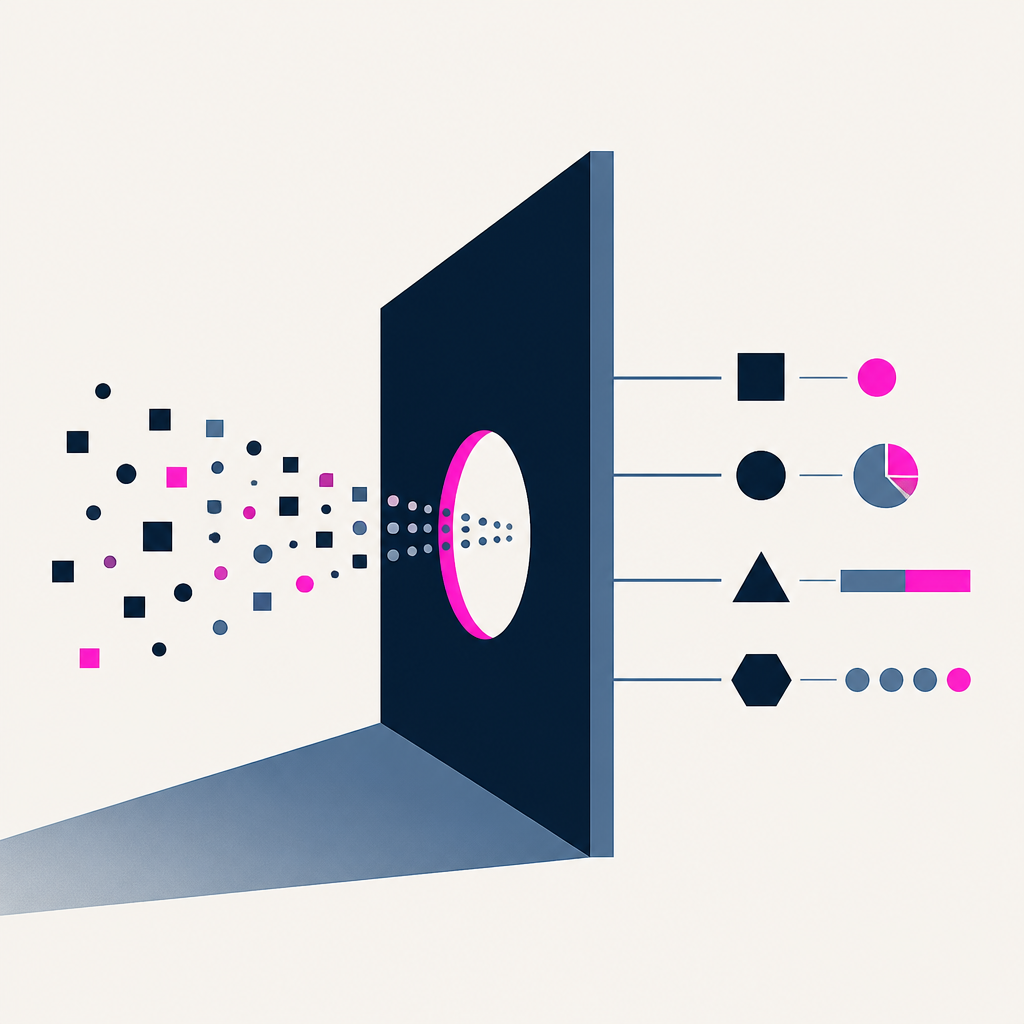
TypeSafe AI has launched Jev, its first System One model, and the pitch is refreshingly narrow. It does not try to be another chatty generalist. It takes unstructured state, then returns typed decisions with probabilities attached. Founder Diogo Almeida also has a past stretch at OpenAI, where he worked on the instruction-following research behind ChatGPT.
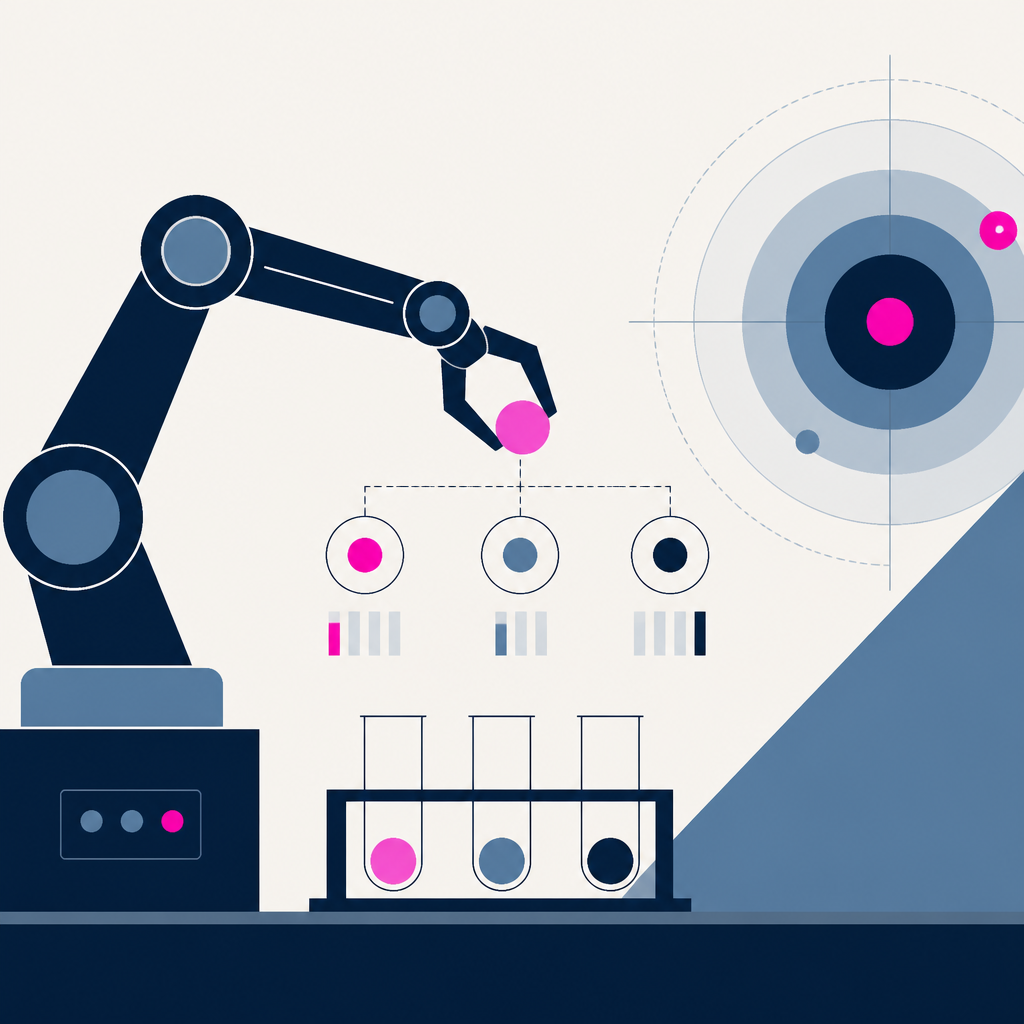
The basic unit is simple: send Jev some text or JSON plus a dictionary of typed questions, and get answers back in parallel. TypeSafe defines three primitives. Choice picks one option from a list and returns a probability for each option plus confidence. Score maps the state onto ordered rubric levels. Noul returns the probability that a statement is true. The whole thing is trained with Reinforcement Learning for Calibrated Decisions, so the confidence number is meant to mean something, not just decorate the result.
That design makes Jev useful inside agent loops, where the hard work is often not generation but judgment. TypeSafe’s examples cover routing, safety checks, retrieval, and verification. ModelRouterMiddleware can score request difficulty and send work to a fast model or a stronger one. Skill suggestion can pick one skill from a large catalog. Function calling can map a plain-language request to a function name and a closed set of arguments. Other cookbooks use it for ticket triage, tool-call risk gating, read-only auto-approval, secret-leak checks, prompt-injection screening, reranking, and citation verification.
The numbers TypeSafe puts forward are aggressive. On its own workflow evals, the company claims Jev is 193.6x faster and 444.6x cheaper, with GPT-6 Astra and Fable 5.1 used as reference answers. It also says Choice supports up to 255 options. On OpenRouter’s Banking77 test, Jev reached 81.0% accuracy versus 84.4% for Claude Opus 5, while being 13x faster at the median and about 1/22 the cost.
And the use cases get more tactile from there. Browser Use’s Jev Ultrafast finished a Google Flights search in about 7.1 seconds. typesafe-computer-use reportedly classifies macOS steps for about $0.0002 each. A mobile setup reached an Uber payment screen in about 21 seconds and 9 actions. TypeSafe’s Doom demo runs at about 10 queries per second and roughly $7 per hour on structured game state. The pattern is obvious: Jev is not trying to write the agent’s diary. It’s trying to keep the agent from wandering off the cliff.
My take — AI-written commentary, not fact-checked reporting
This is the sort of thing AI teams keep rediscovering: most agent failures are decision failures, not writing failures. Jev looks useful precisely because it gives the model less room to be poetic and more room to be right. The industry could use fewer grand “assistant” demos and more boring little judges like this.
Read more about this at: MarkTechPost