
FLUX 3
Model ● Covered in 5 stories + Follow
FLUX 3 is a multimodal foundation model released by Black Forest Labs that generates images, videos, audio, and robot action predictions using a unified architecture trained on all modalities simultaneously. The model generates videos up to 20 seconds with native audio and achieved competitive or preferred performance in human evaluations against other video generation systems like Luma Ray 3.2 and Gemini Omni. Black Forest Labs is rolling out FLUX 3 in phases through early access with plans to release an open-weights developer version.
Updated 5 August 2026
Specifications
No specifications recorded yet.
Latest developments
 Deep Learning Weekly: Issue 466
Deep Learning Weekly · 1 month ago ·
18
 Opus 5 >> Fable 5
Ben's Bites · 1 month ago ·
28
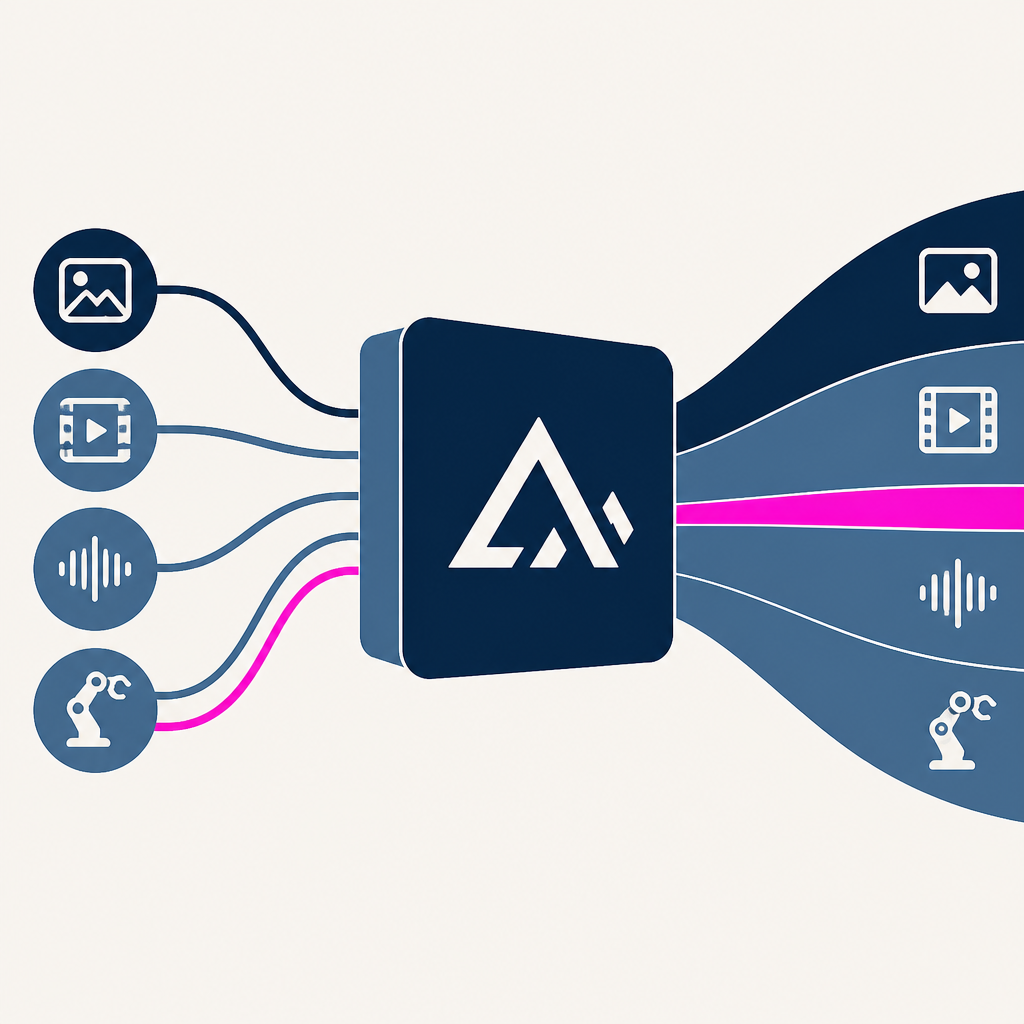 Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction
MarkTechPost · 1 month ago ·
16
FLUX 3 Expands Black Forest Labs' Image Generation Capabilities
Black Forest Labs · 1 month ago ·
16
[AINews] Black Forest Labs FLUX 3 - Multimodal Flow Models that beat Seedance 2.0, Gemini Omni and Grok Imagine, and FLUX-mimic video-action robotics model
Latent Space · 1 month ago ·
12
July 2026
Anthropic releases Claude Opus 5 at half the price of Fable 5 with comparable performance Model release
Black Forest Labs releases FLUX 3 multimodal model for image, video, audio, and robot control Model release
- Deep Learning Weekly: Issue 466
- Opus 5 >> Fable 5
- Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for Image, Video, Audio and Robot Action Prediction
- FLUX 3 Expands Black Forest Labs' Image Generation Capabilities
- [AINews] Black Forest Labs FLUX 3 - Multimodal Flow Models that beat Seedance 2.0, Gemini Omni and Grok Imagine, and FLUX-mimic video-action robotics model
Relationships
Products & technology
- Black Forest Labs develops this model · 4 sources
- FLUX-mimic derived from this model · 1 source