
Sarvam AI Releases Saaras V4: A Speech-to-Text Model for All 22 Indian Languages and Global English
MarkTechPost Asif Razzaq
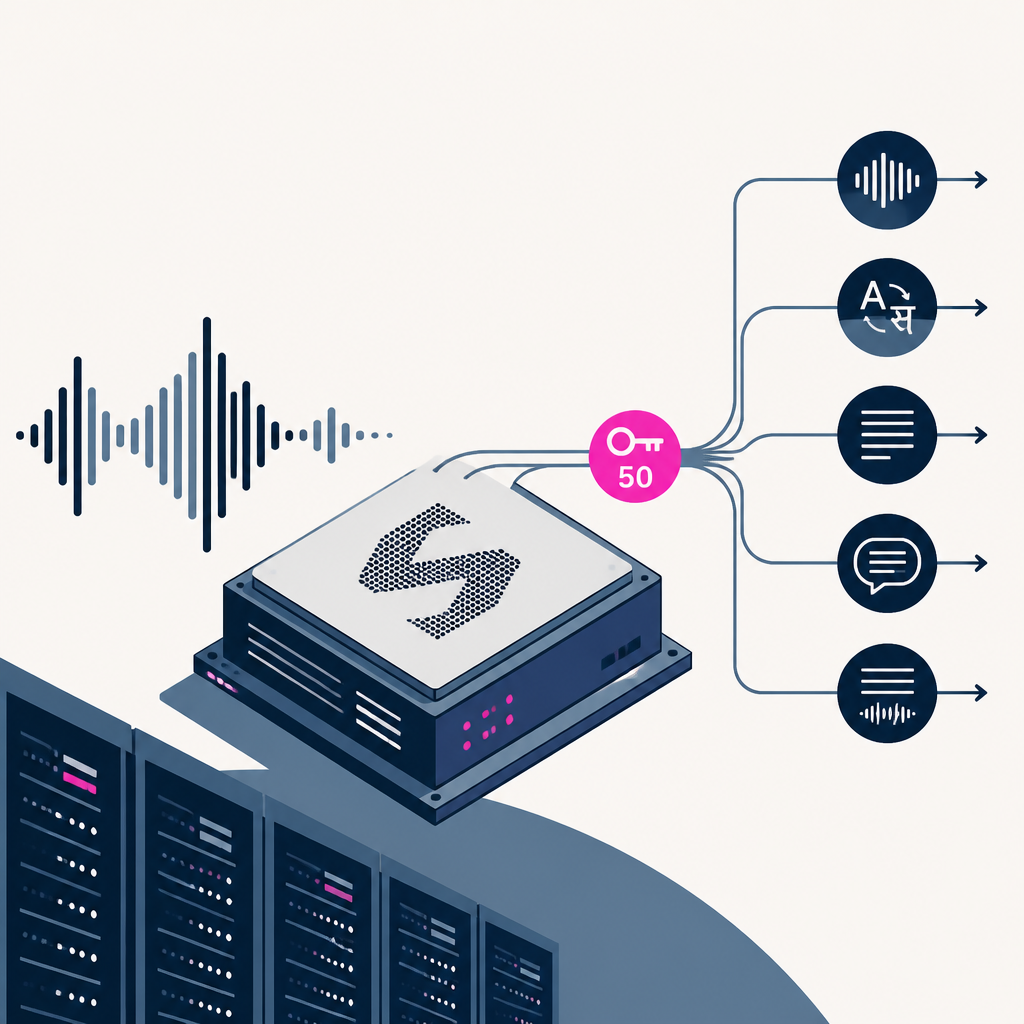
Sarvam AI launched Saaras V4, a speech model for all 22 Indian languages plus English. It’s API-only for now, and self-hosting still points to v3.
Based on reporting by MarkTechPost, Asif Razzaq — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
Sarvam AI has shipped Saaras V4, the latest version of its speech recognition system, and it’s aiming wide. The model covers all 22 scheduled Indian languages, plus English with global accents. Sarvam says it gets state-of-the-art accuracy across those languages, though the company’s own numbers haven’t been independently reproduced yet.
The new model is built as an encoder-decoder system. An audio encoder turns sound into embeddings, then a temporal-downsampling adapter compresses that sequence so it fits the decoder’s context window. The decoder is Sarvam-3B, a 3B-parameter hybrid state-space language model trained from scratch in-house. In practice, it reads audio features alongside a text prompt and generates the transcript token by token.
The company is also pushing V4 as a single model with multiple faces. Through the API, the same input can produce native-script transcription, verbatim output, codemixed text, transliteration, or English translation. Sarvam’s pitch is that handling all of that inside the model avoids extra post-processing, which is where errors tend to pile up.
There’s also a new keyterm prompting feature, limited to Saaras V4. Users can send up to 50 terms in a JSON list, and those terms bias recognition without guaranteeing the final output. Sarvam says this helps with things like keeping a brand name such as PhonePe in Latin script when using codemix mode.
On the benchmark side, Sarvam says V4 leads the models it tested on English, Indian languages, and noisy audio. It reports the lowest average WER across seven English datasets, 16.03% WER on IndicContextEval’s L5 keyword-prompting setting, and a language ID error of 2.9% across the top 10 Indian languages. The service is available now through Sarvam’s API with model="saaras:v4", while the SageMaker self-hosting docs still cover Saaras v3. Pricing starts at ₹30 per hour for real-time, streaming, and batch use, or ₹45 per hour with diarization.
My take — AI-written commentary, not fact-checked reporting
This is the kind of release that matters more than another flashy demo. One model covering all 22 Indian languages is the real story here, not the benchmark victory lap. The catch, as usual, is the closed API-first approach: useful, polished, and a little too convenient for anyone hoping to inspect the thing instead of just renting it.
Read more about this at: MarkTechPost