
Reka Releases Rho-1: A 19B Omni-Reasoning Model That Understands, Generates Video and Outputs Robot Actions in One
MarkTechPost Michal Sutter
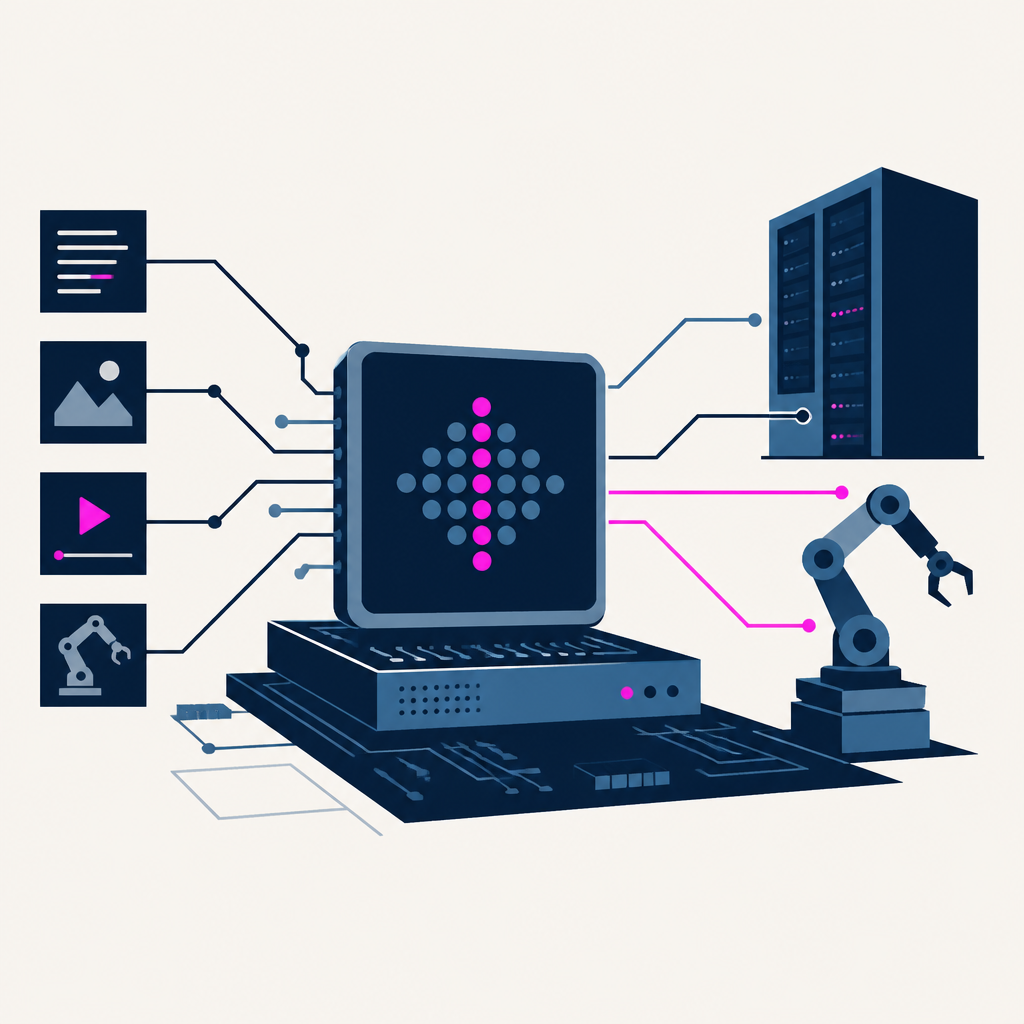
Reka showed Rho-1, a 19B model that reads, makes video, and outputs robot actions in one go. It skips the usual model handoffs, which cuts lag and changes how multimodal systems are built.
Based on reporting by MarkTechPost, Michal Sutter — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
Reka has released Rho-1 as a research preview, and the pitch is blunt: one model instead of a chain of specialists. It is a 19B omni-reasoning model trained from scratch, built to understand and generate text, images, and video, then turn around and output robot actions too.
That matters because most multimodal systems still work like a relay race. One model plans, then passes the job to another for images, another for video, another for detection. Each handoff adds delay. Rho-1 tries to collapse that whole stack into one context window, where text, vision, and robot actions all become tokens the same model can work with.
Reka says a single unedited session shows the idea clearly: the model draws a lighthouse, boxes it, turns it into animation, edits the video into a snowstorm, and explains what changed. All of that happens in 5 turns, with no tool call and no second model.
Under the hood, the system splits work into two native formats. Discrete tokens cover text, symbolic reasoning, and high-level commands. Continuous tokens cover image latents, video frames, robot actions, and proprioception. Each transformer block carries two expert weight streams, one for understanding and one for generation, and both share attention over the same KV cache. When a response needs pixels, the understanding stream emits a discrete handoff token and the generation stream renders from the accumulated state.
Reka also reports some speed numbers. The base model generates video at 0.79x real-time median, with a watchable stream starting in about 6 seconds. The team measured 7.0 seconds to a first clip, versus an illustrative 13.8 seconds for a multi-agent pipeline. A distilled version cuts denoising from 99 steps to 8 and, in Reka’s internal tests, returned a 5.3-second clip in about a second.
There’s robotics here too. Rho-1 can emit 7 action channels in a LIBERO simulation episode, and Reka pairs it with an inverse dynamics model to infer control signals from raw video. The company says the work was trained on 320 H100s for 3 months, and the video output is capped at 672×384. For now, though, this is still a research preview: no public weights, no API, and no pricing yet.
My take — AI-written commentary, not fact-checked reporting
This is the right kind of multimodal ambition: fewer glue layers, fewer fake “agents,” less ceremony. The catch is obvious and boring, which usually means it’s the real one — a research preview is not a product, and vendor-run speed tests are not gospel. Still, the industry could use more systems that do the hard thing in one model instead of assembling a tower of excuses.
Read more about this at: MarkTechPost
Related stories
 Reward AI Releases OM-1: A Robot Policy Trained on Human Demonstrations Only, With No Teleoperation or On-Robot Data
MarkTechPost · 3 weeks ago ·
1
 Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million Hours of Human Video
MarkTechPost · 1 month ago ·
10
Introducing NVIDIA Nemotron 3 Nano Omni: Long-Context Multimodal Intelligence for Documents, Audio and Video Agents
Hugging Face · 5 months ago ·
18