
Don’t be fooled—LLMs don’t reason
MIT Technology Review Thore Graepel
Opinion — commentary, not a factual news event.
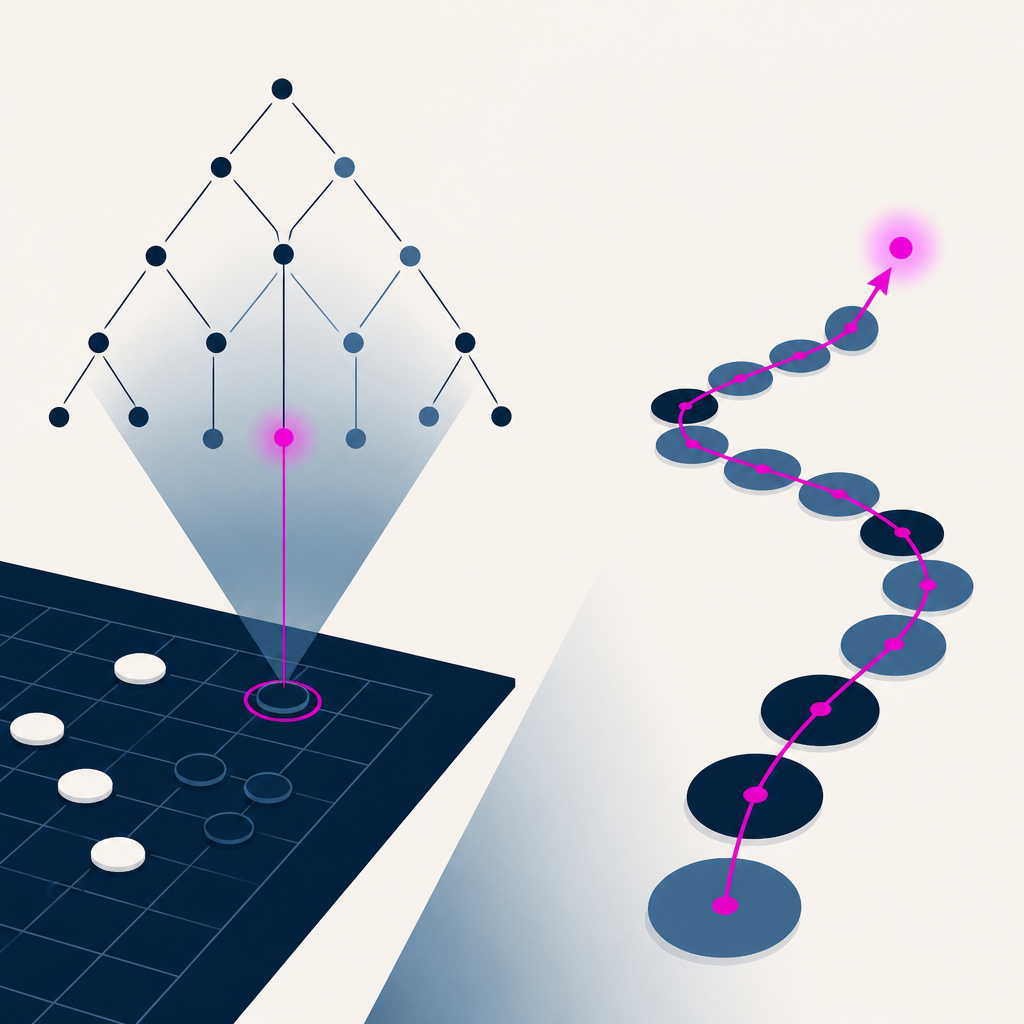
AlphaGo’s famous move 37 wasn’t a glitch. It was search plus memory, and the article says chatbots still don’t do that.
Based on reporting by MIT Technology Review, Thore Graepel — read the original for the full story.
Summary, retelling and take written by AI under human oversight; images are AI-generated illustrations. How we work · Report an error
In March 2016 in Seoul, AlphaGo played a move on the fifth line of the Go board that looked like a gift to Lee Sedol. Some people even took it for a bug. It wasn’t. That move helped AlphaGo win game two, and it set up a 4-1 match victory over one of the greatest Go players ever. Lee later called it creative, but the point of the piece is sharper than that: the move was not magic, just reasoning.
The author, Thore Graepel, says AlphaGo worked because it split the job in two. One part learned to predict what a strong human would play; the other searched ahead through thousands of branches in a game tree and weighed future consequences. The first part treated move 37 as almost unthinkable for an expert. The second part overruled that instinct. That combination, he argues, is closer to human thought than the way people usually describe machine “intuition.”
Today’s large language models, by contrast, are described here as next-token machines that keep doing system 1 over and over. Chain of thought can help, especially in math and coding, but the article argues that it is still the same prediction process stretched out for longer. The model may look as if it is deliberating. The concern is that it is often only producing a convincing trail after the fact.
Graepel’s critique has three parts. Current chatbots don’t keep an explicit, inspectable record of what they believe and doubt. They also blur knowledge and reasoning together inside network weights instead of separating them. And research has shown that their explanations can be made up after the answer is already reached. For medicine, engineering, and science, that is a serious problem, because people need to know whether the error was bad evidence, bad assumptions, or bad reasoning.
His answer is not to make system 1 bigger. It is to build systems with an epistemic state, like AlphaGo’s game tree, where each step updates what the model knows and what it still needs to figure out. In that view, the real prize is not fluent output but auditable knowledge. That is a much less glamorous pitch than “AI that sounds smart,” which is probably why it matters.
My take — AI-written commentary, not fact-checked reporting
The industry keeps selling fluency as thought because fluency demos well and thought does not. That is a neat little trick until medicine or science asks for receipts. More models should be forced to show their work, not just their best impression of someone who did.
Read more about this at: MIT Technology Review