
CLIP
Model ● Covered in 9 stories + Follow
CLIP is a vision-language model designed to connect text and images in a shared embedding space for tasks such as zero-shot image classification. Recent coverage highlights its use as a foundational vision encoder in larger multimodal systems and as an embedding backbone for applications like visual document indexing and image search. The model has also been studied both in variants such as Chinese CLIP for cross-modal retrieval and in analyses that examine neuron-level behavior consistent across different representations of the same concept.
Updated 10 September 2026
Specifications
No specifications recorded yet.
Latest developments
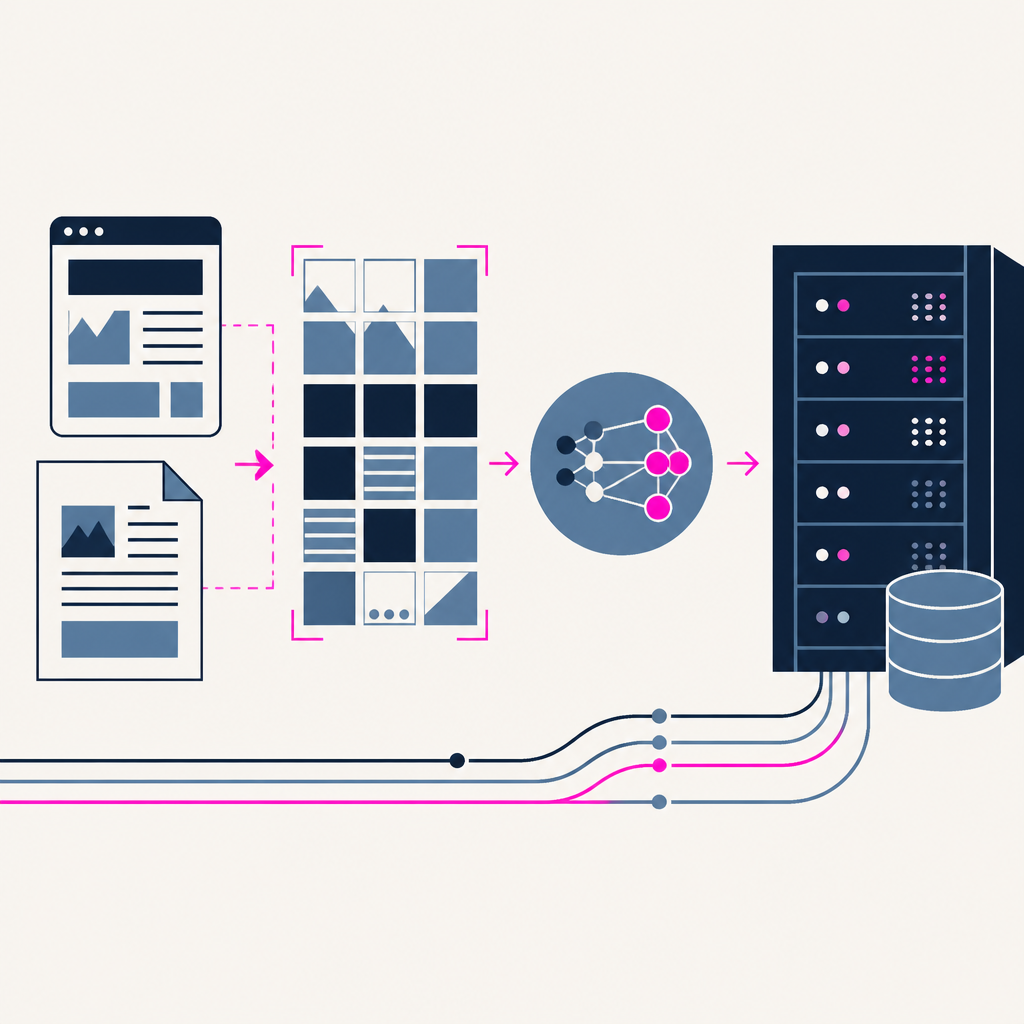 Pixel-Native RAG: A Practical Guide to Visual Document Indexing
MarkTechPost · 1 month ago ·
49
Multimodality and Large Multimodal Models (LMMs)
Chip Huyen · 2 years ago ·
50
Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese
GitHub Pages · 3 years ago ·
43
Text-to-Image: Diffusion, Text Conditioning, Guidance, Latent Space
Eugene Yan · 3 years ago ·
17
Image search with 🤗 datasets
Hugging Face · 4 years ago ·
30
Multimodal neurons in artificial neural networks
OpenAI · 5 years ago ·
13
Scaling Kubernetes to 7,500 nodes
OpenAI · 5 years ago ·
41
August 2026
Educational Tutorials on Multimodal RAG Systems Published Research publication
- Luce: Relightable Gaussians for 3D Asset Generation
- Pixel-Native RAG: A Practical Guide to Visual Document Indexing
October 2023
December 2022
November 2022
March 2022
March 2021
January 2021
Relationships
Products & technology
- OpenAI develops this model · 3 sources
- Integrated with Flamingo · 1 source
- Integrated with LLaVA · 1 source
- Chinese CLIP derived from this model · 1 source